Section design examples

6,918 sections captured and categorized, from 2,587 funnels x-rayed.
Section

Showing 24 of 6918 sections

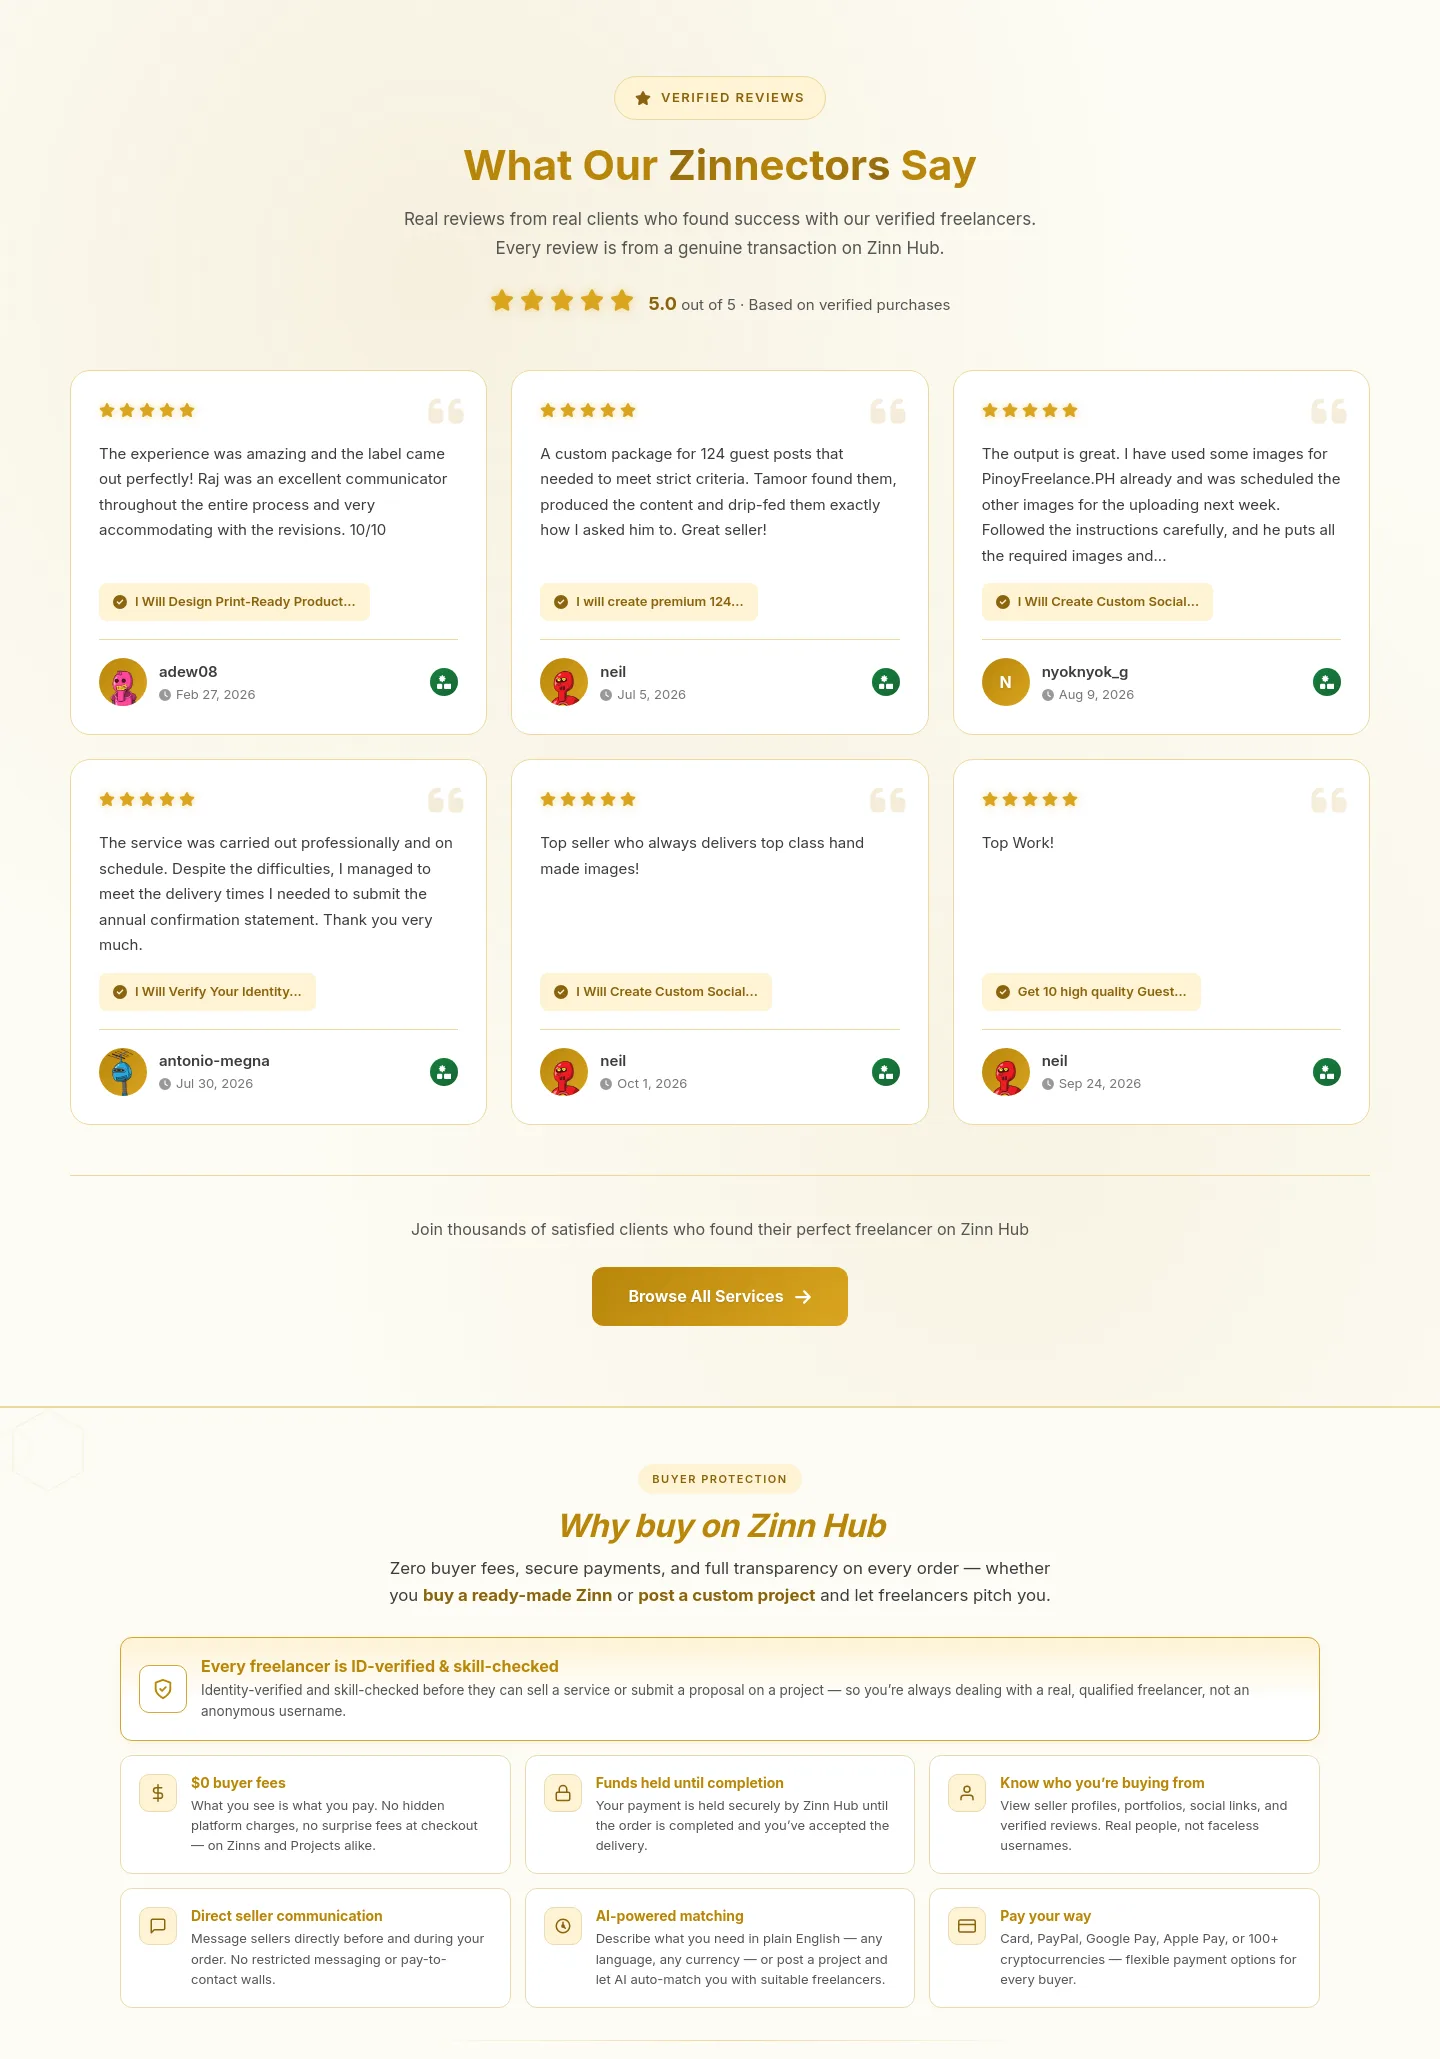
zinnhub.com — a real Reviews section
zinnhub.com · Reviews
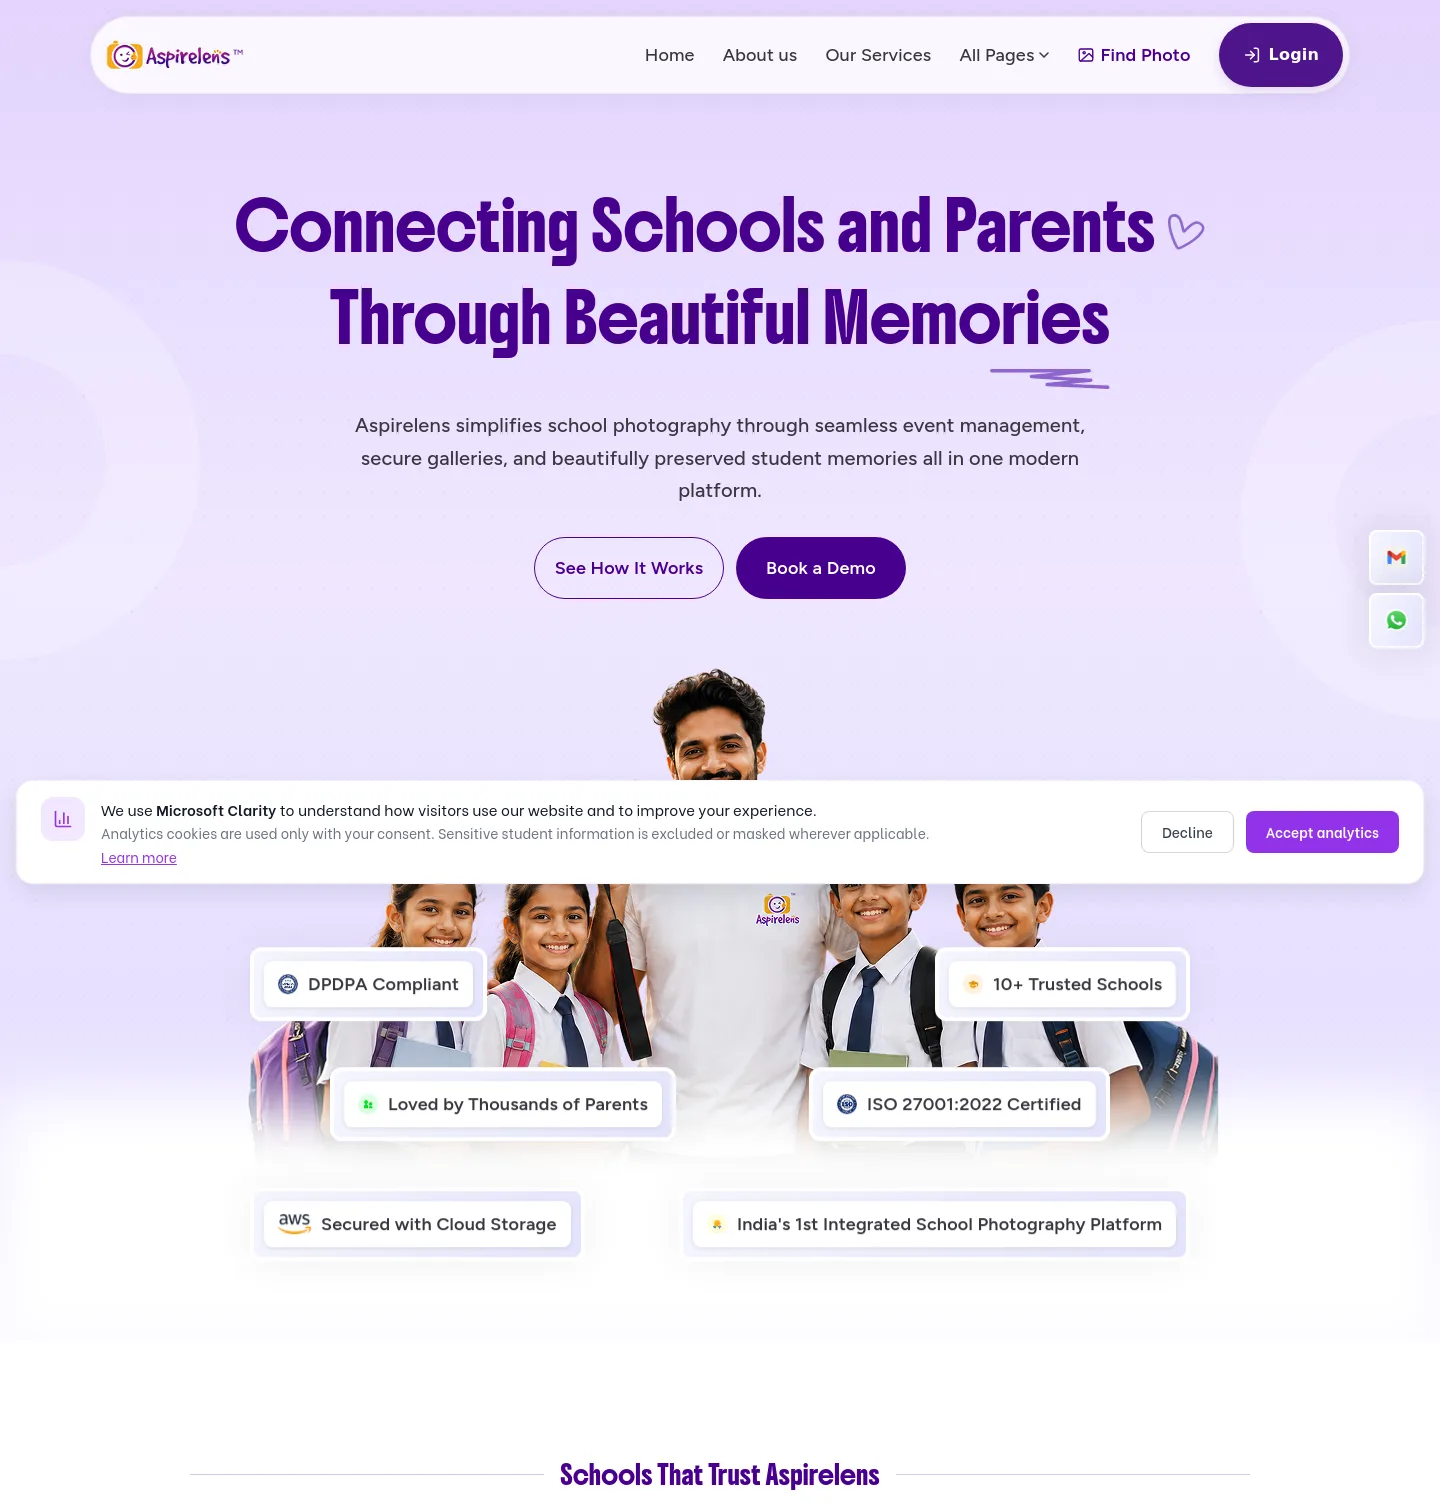
aspirelens.com — a real Hero section
aspirelens.com · Hero
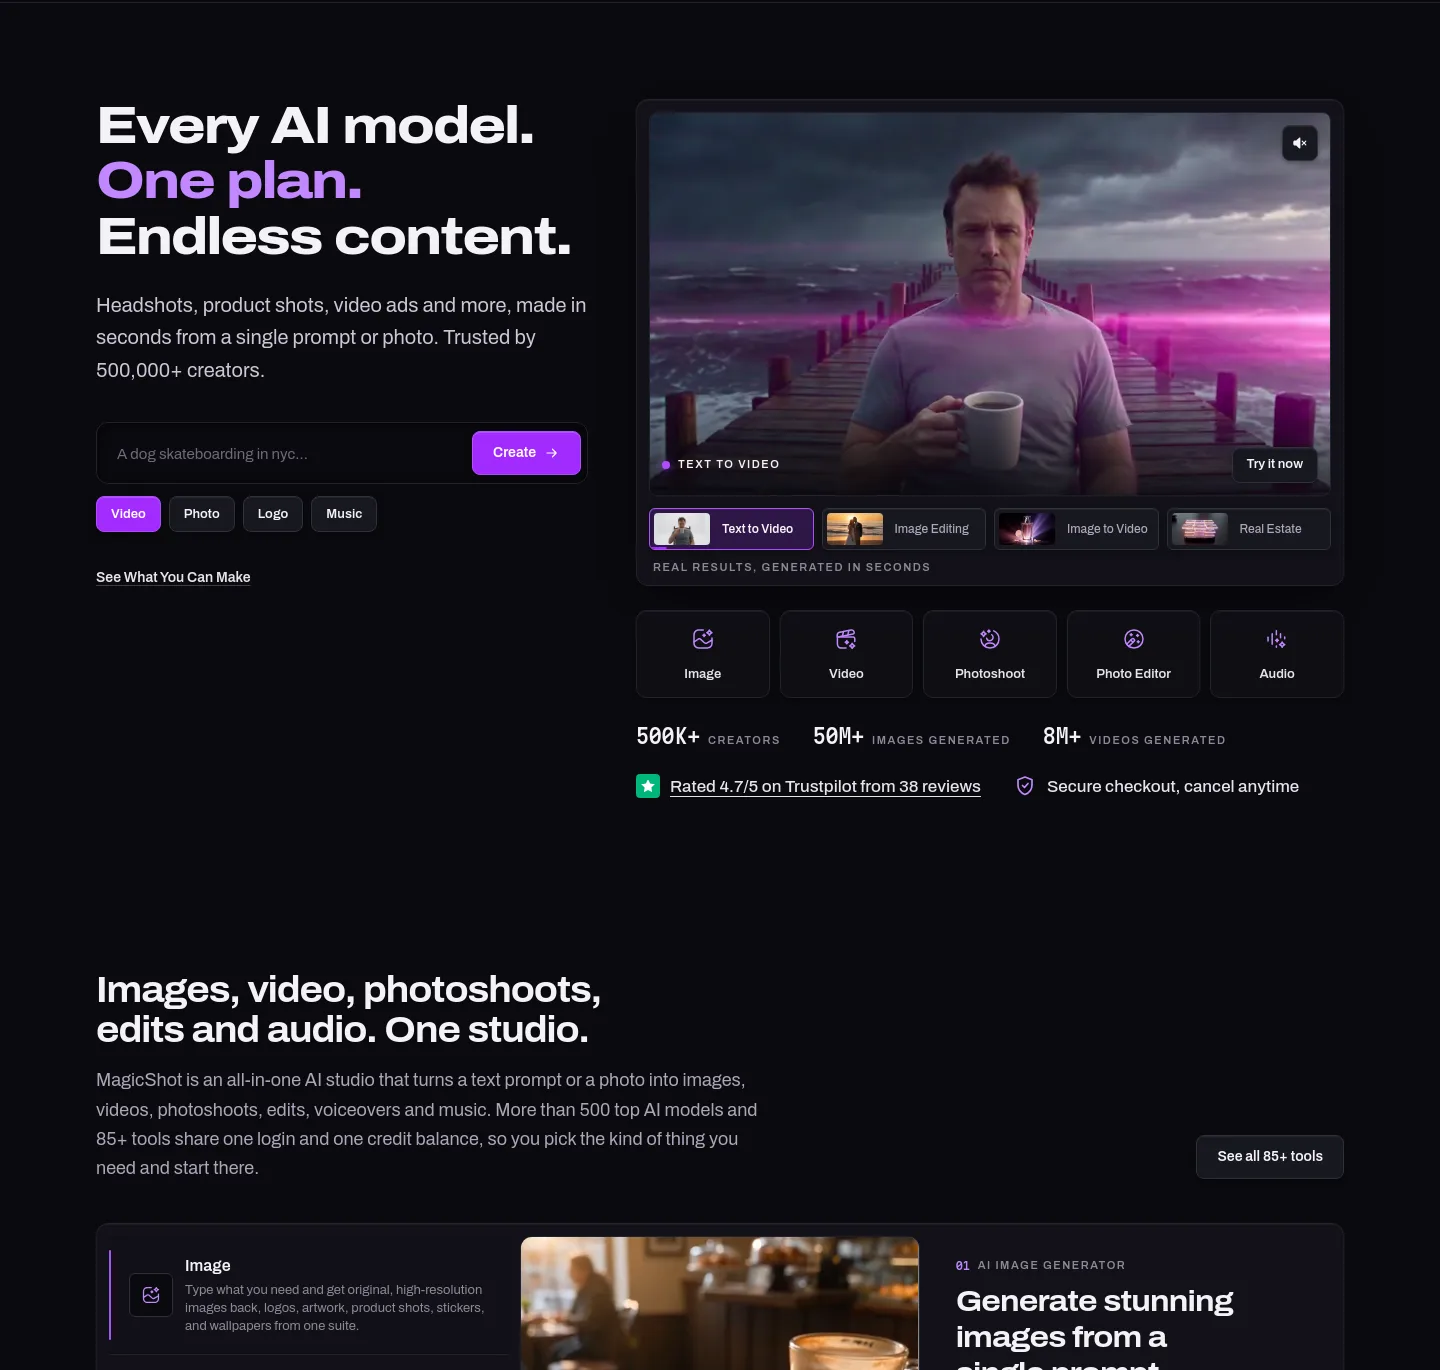
magicshot.ai — a real Hero section
magicshot.ai · Hero
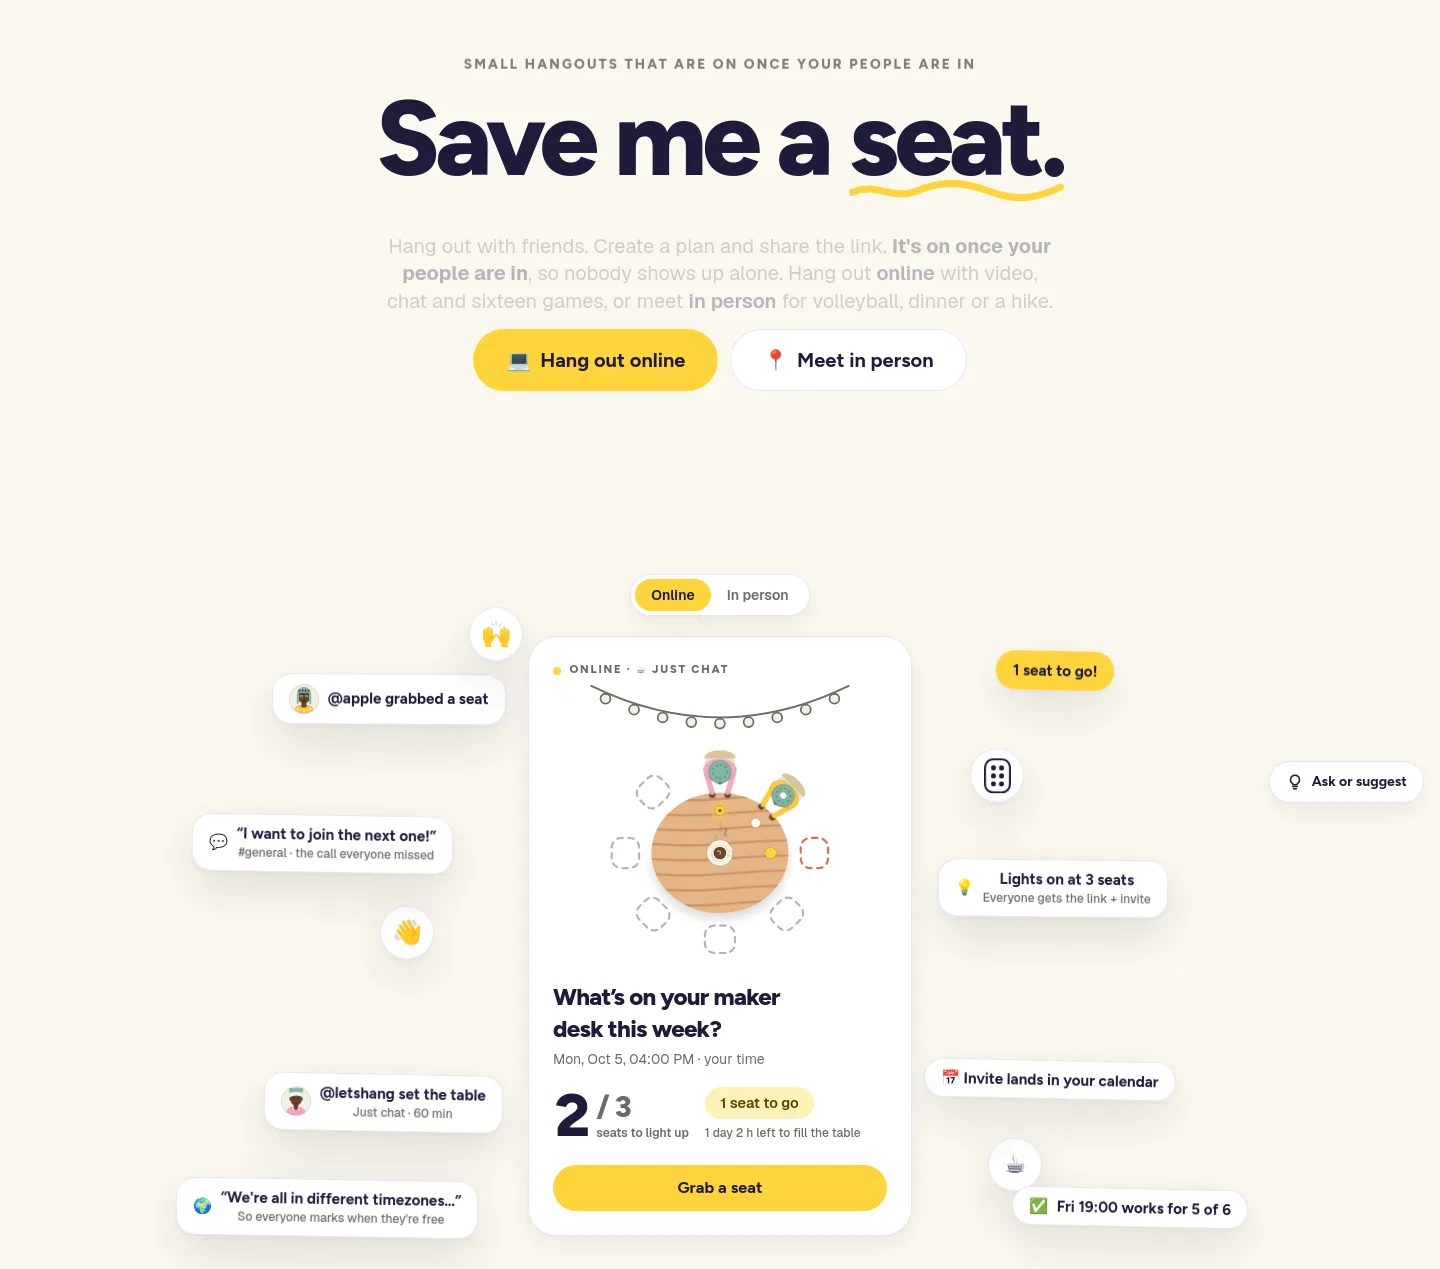
letshang.io — a real Hero section
letshang.io · Hero
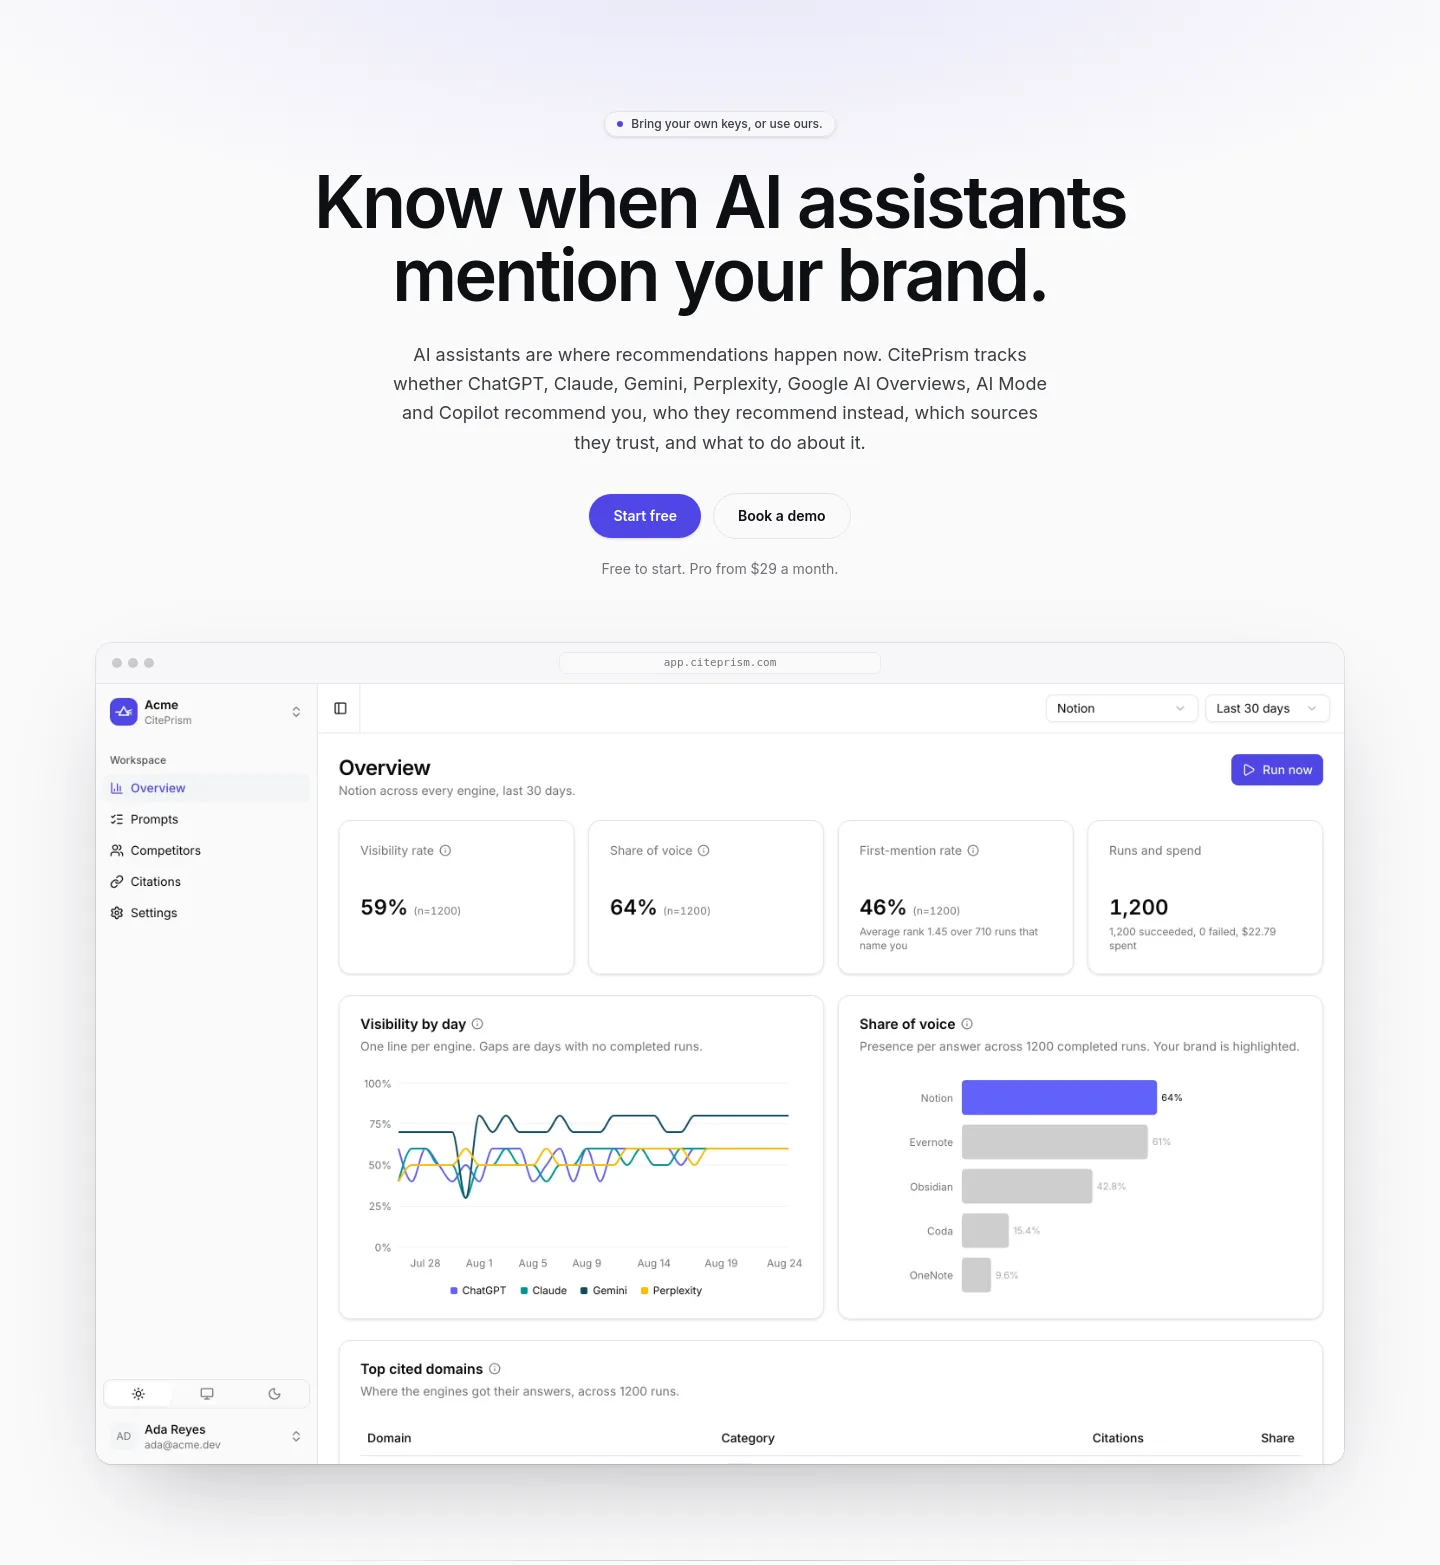
citeprism.com — a real Hero section
citeprism.com · Hero
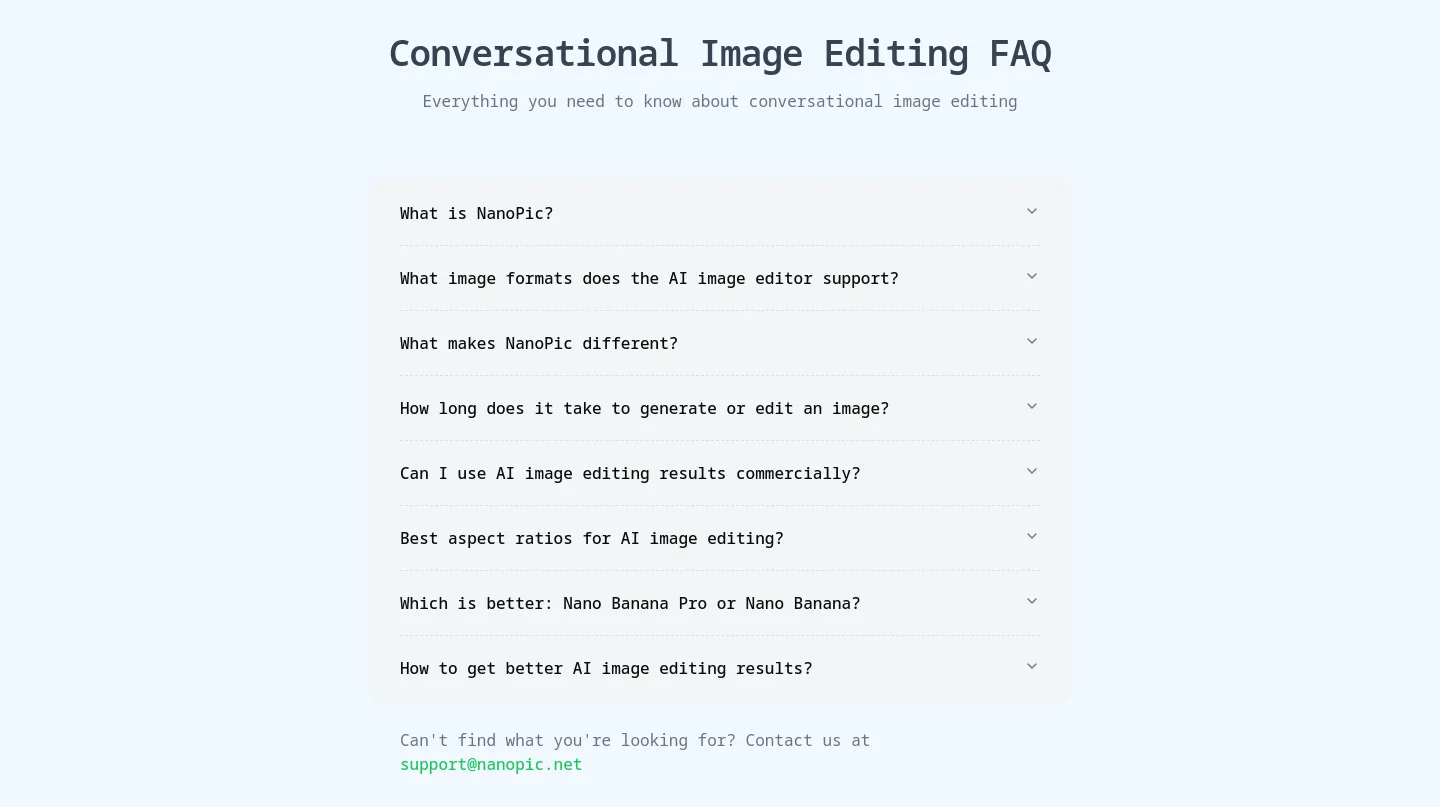
nanopic.net — a real FAQ section
nanopic.net · FAQ
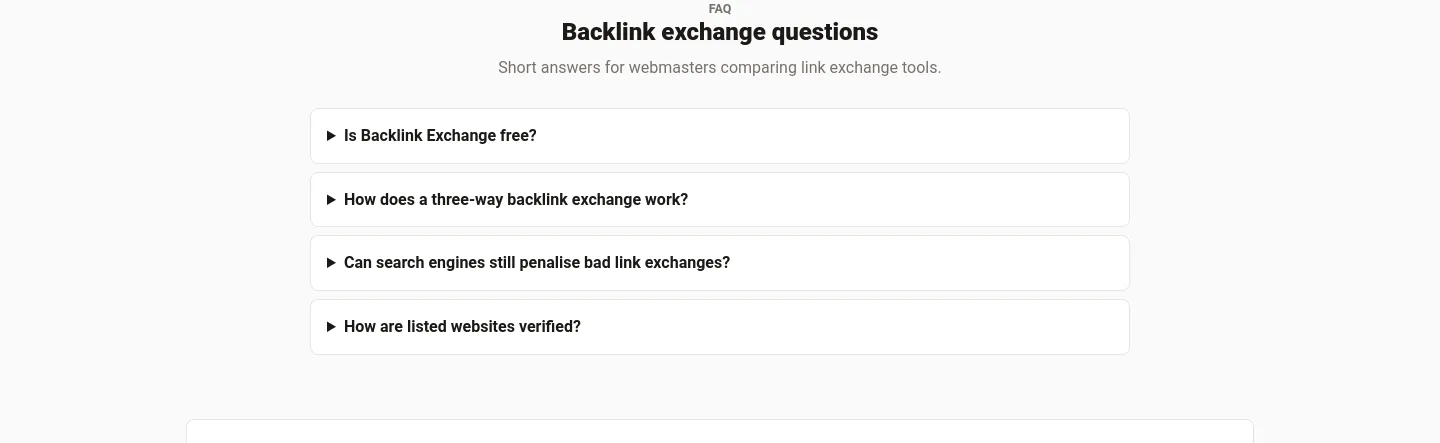
backlinkexchange.org — a real FAQ section
backlinkexchange.org · FAQ
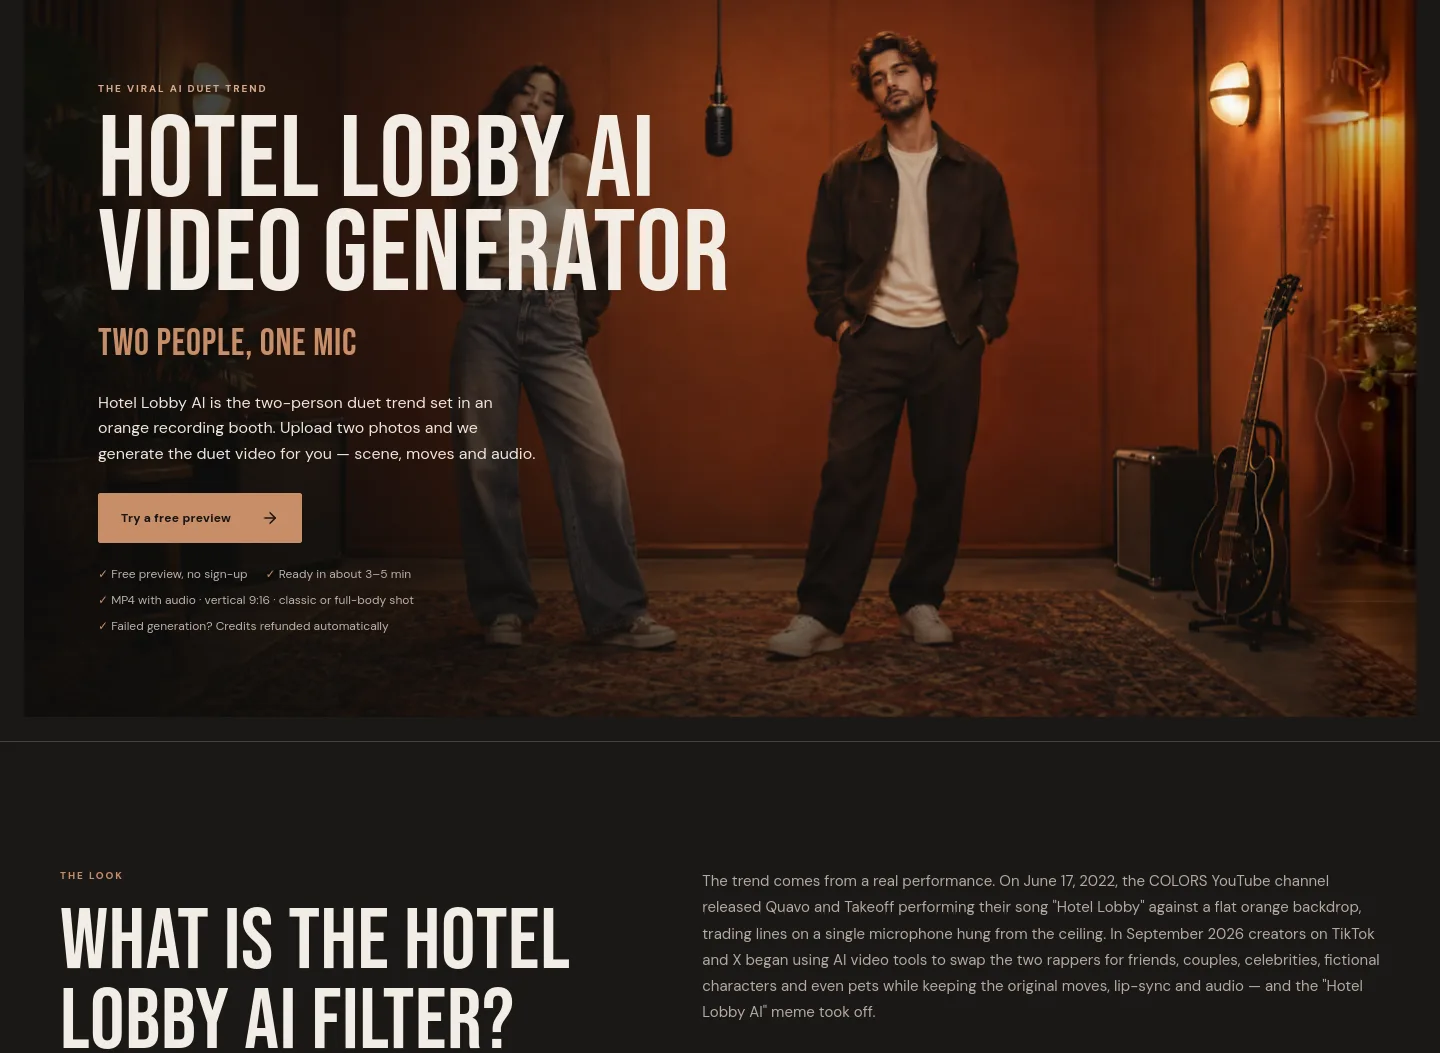
hotel-lobby.org — a real Hero section
hotel-lobby.org · Hero
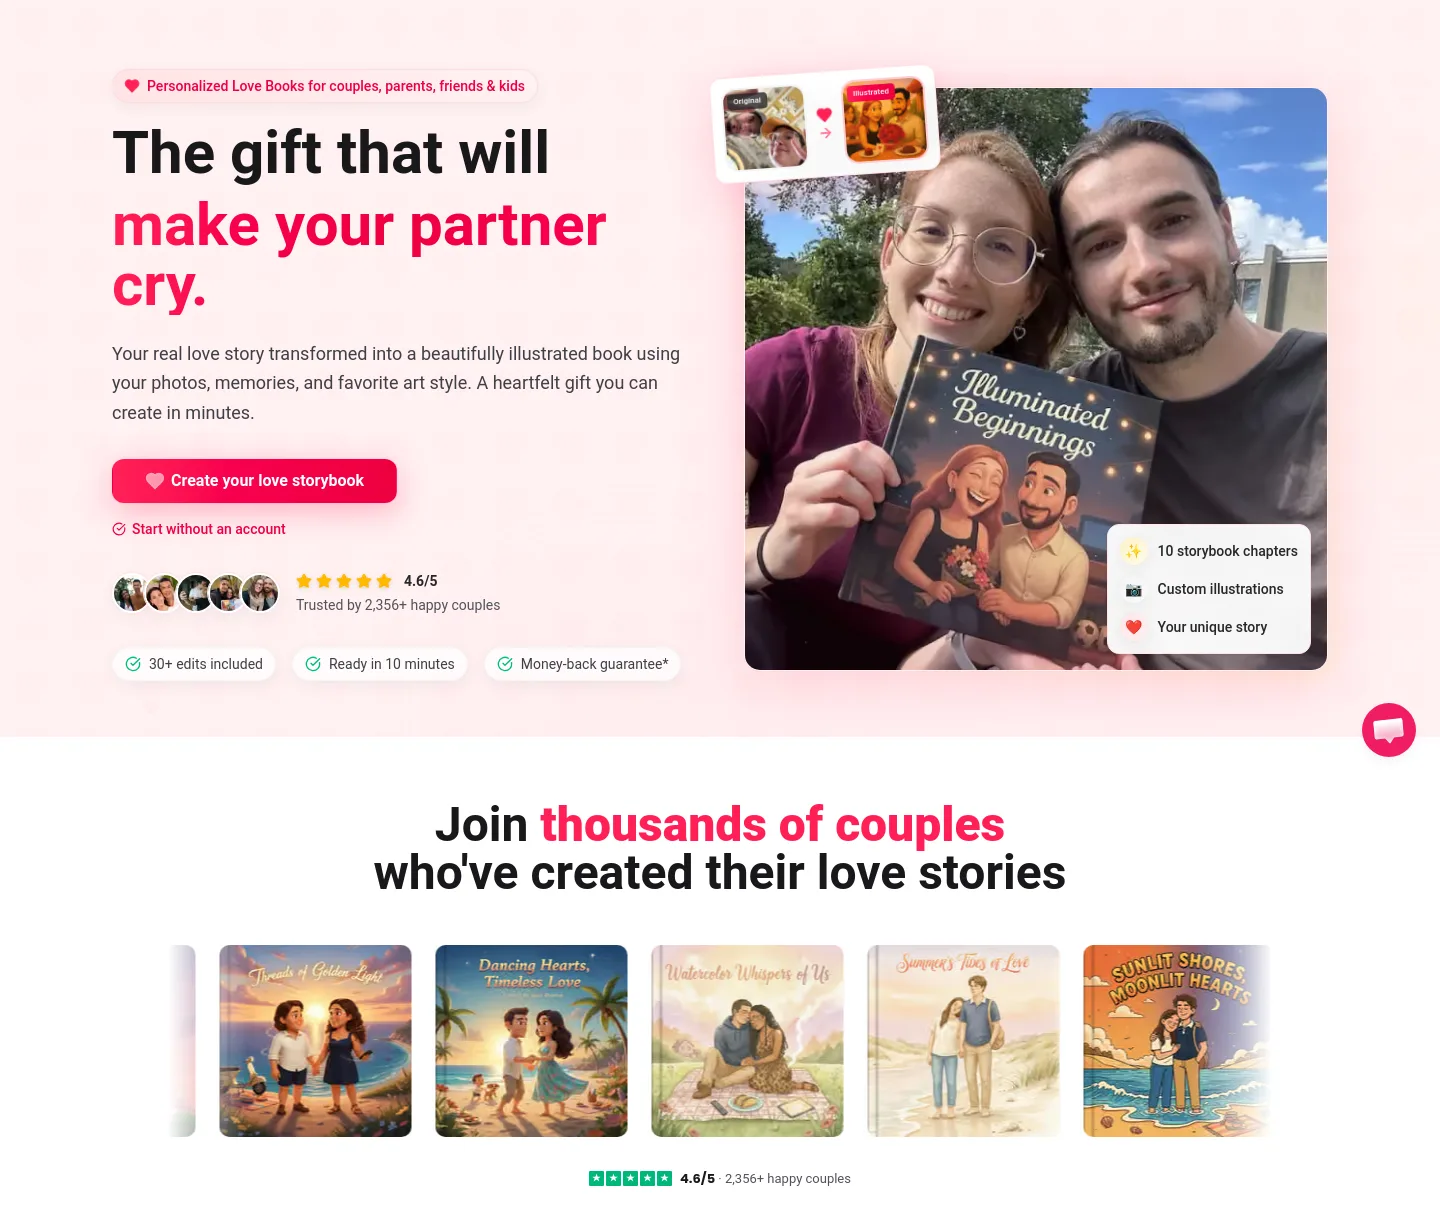
lovetales.ai — a real Hero section
lovetales.ai · Hero
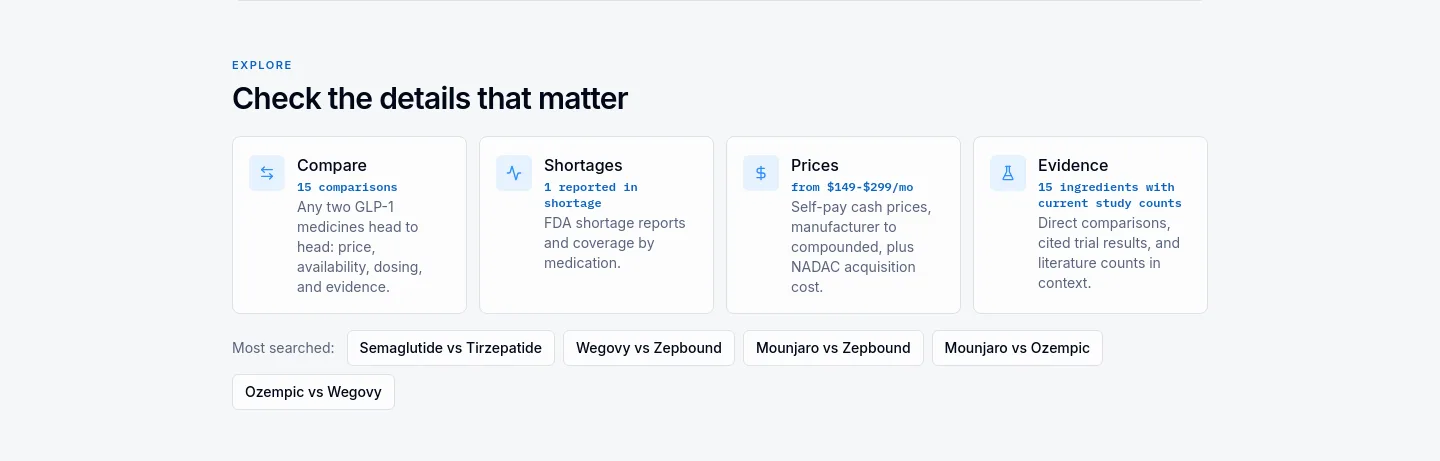
glpcompare.co — a real Pricing section
glpcompare.co · Pricing
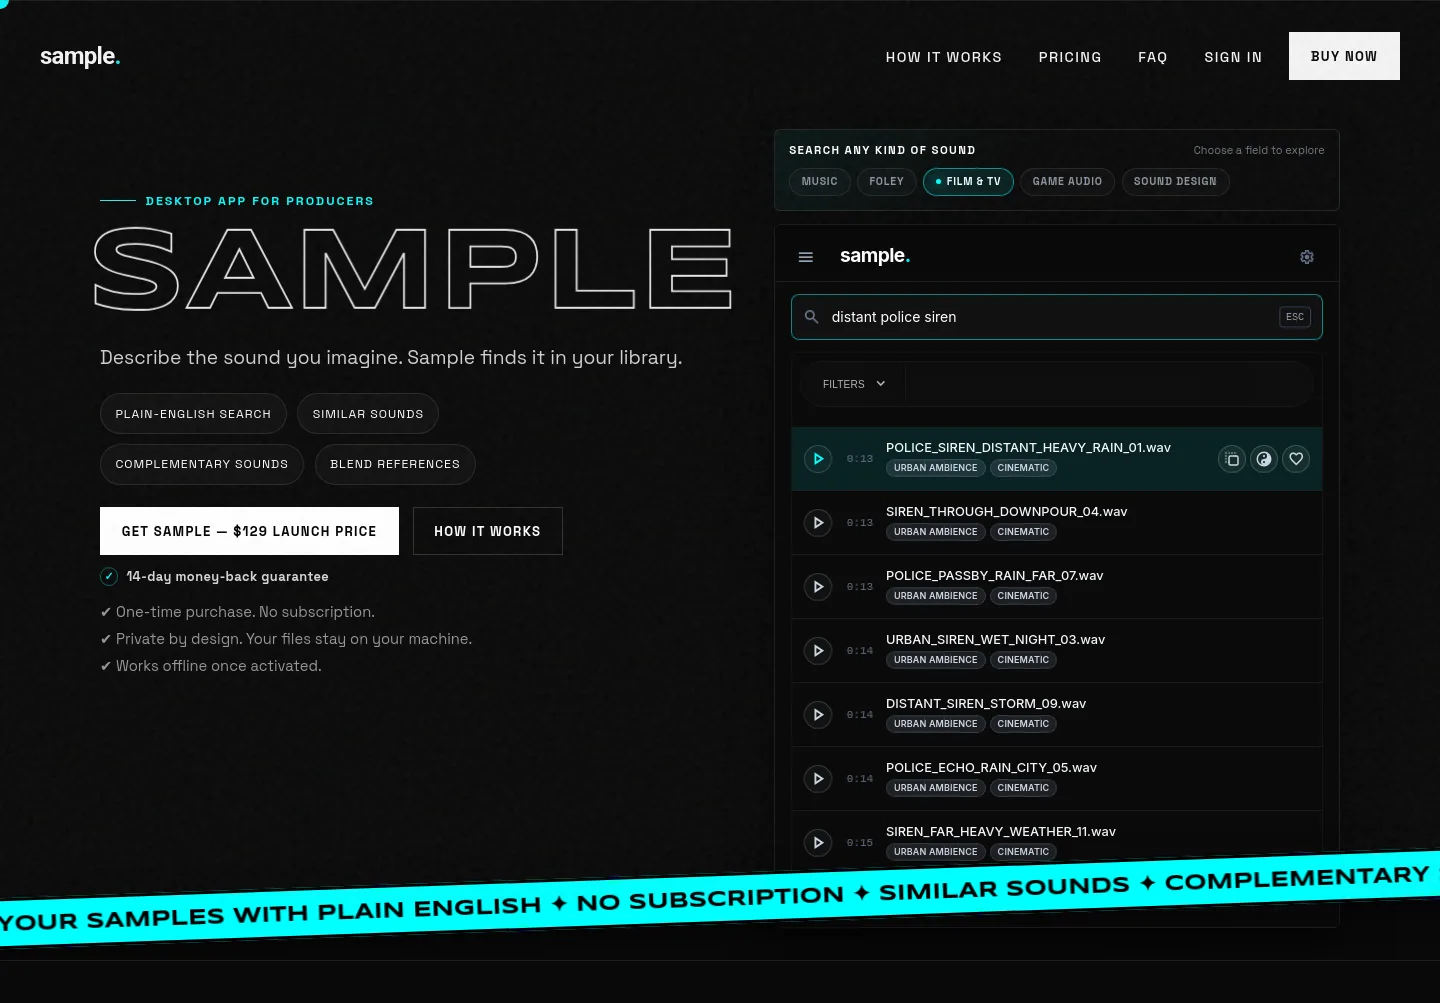
sample.audio — a real Hero section
sample.audio · Hero
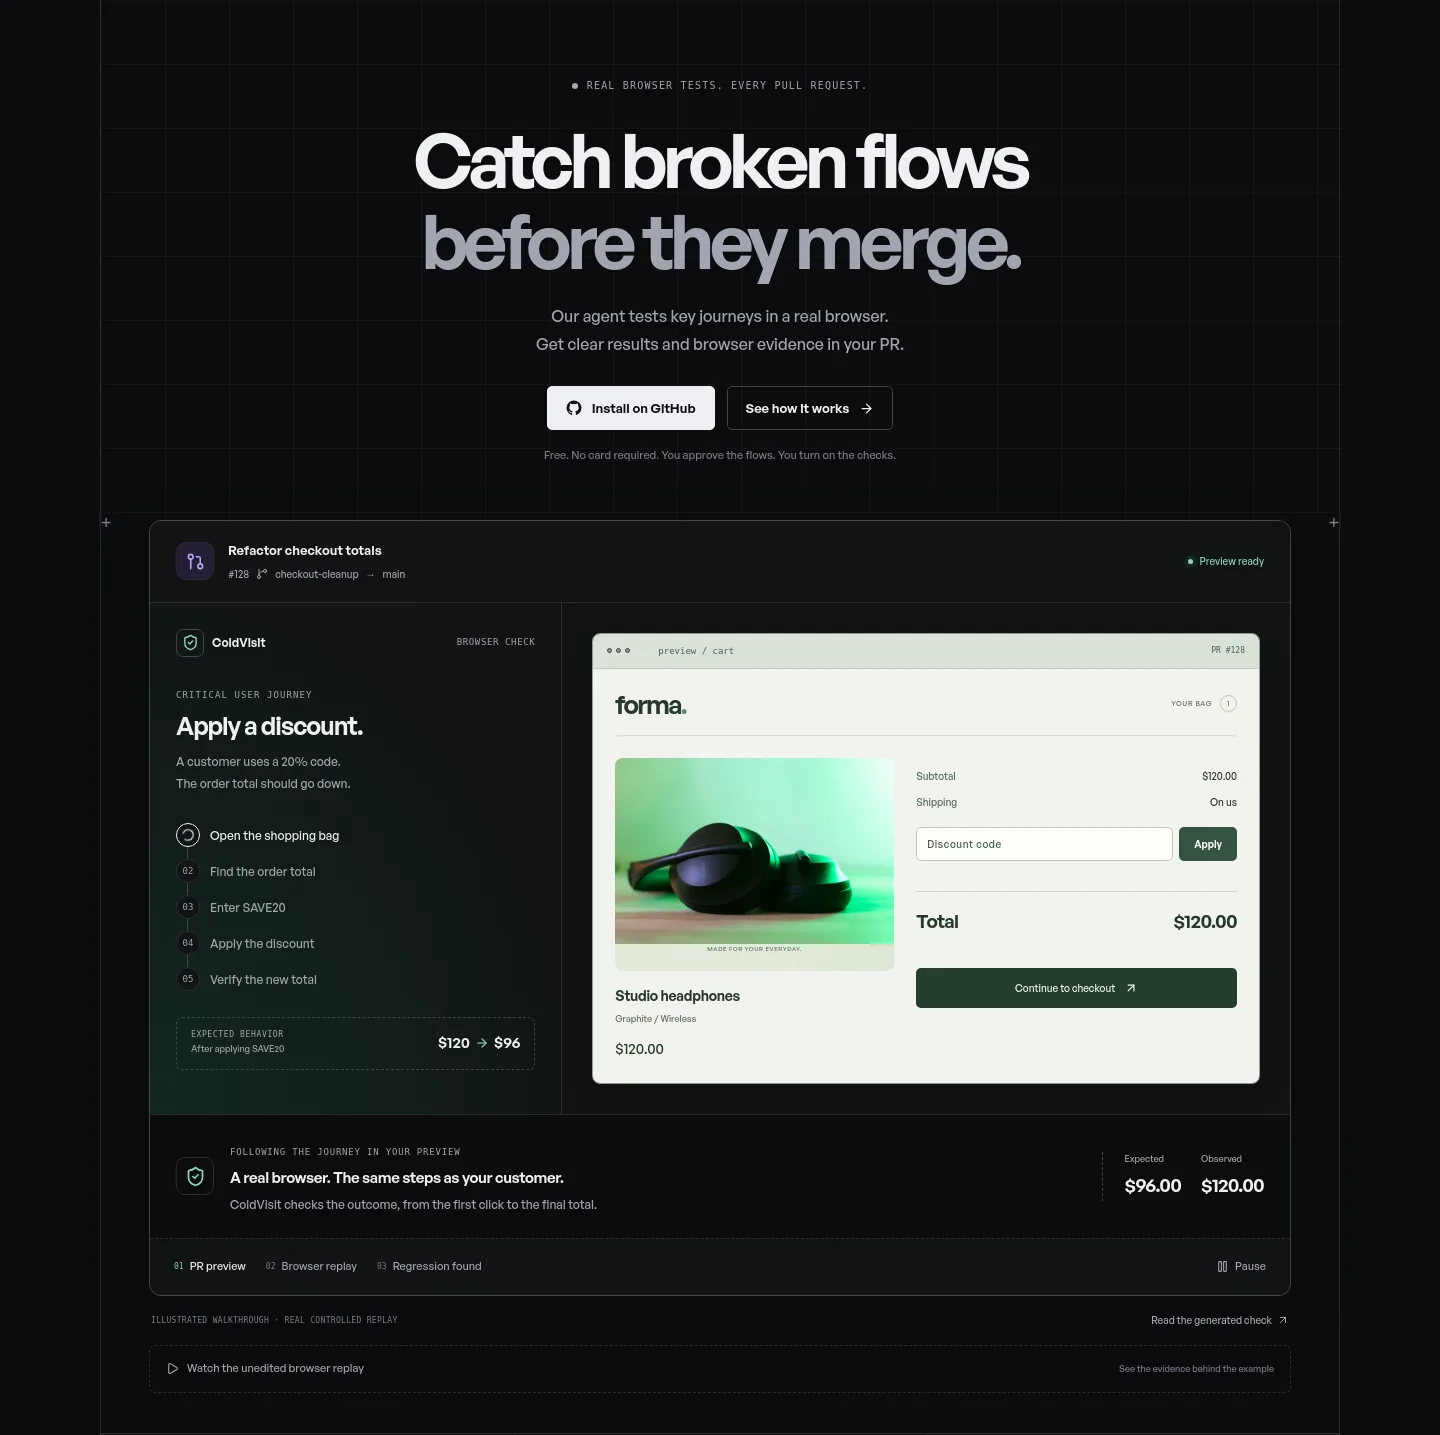
coldvisit.com — a real Hero section
coldvisit.com · Hero
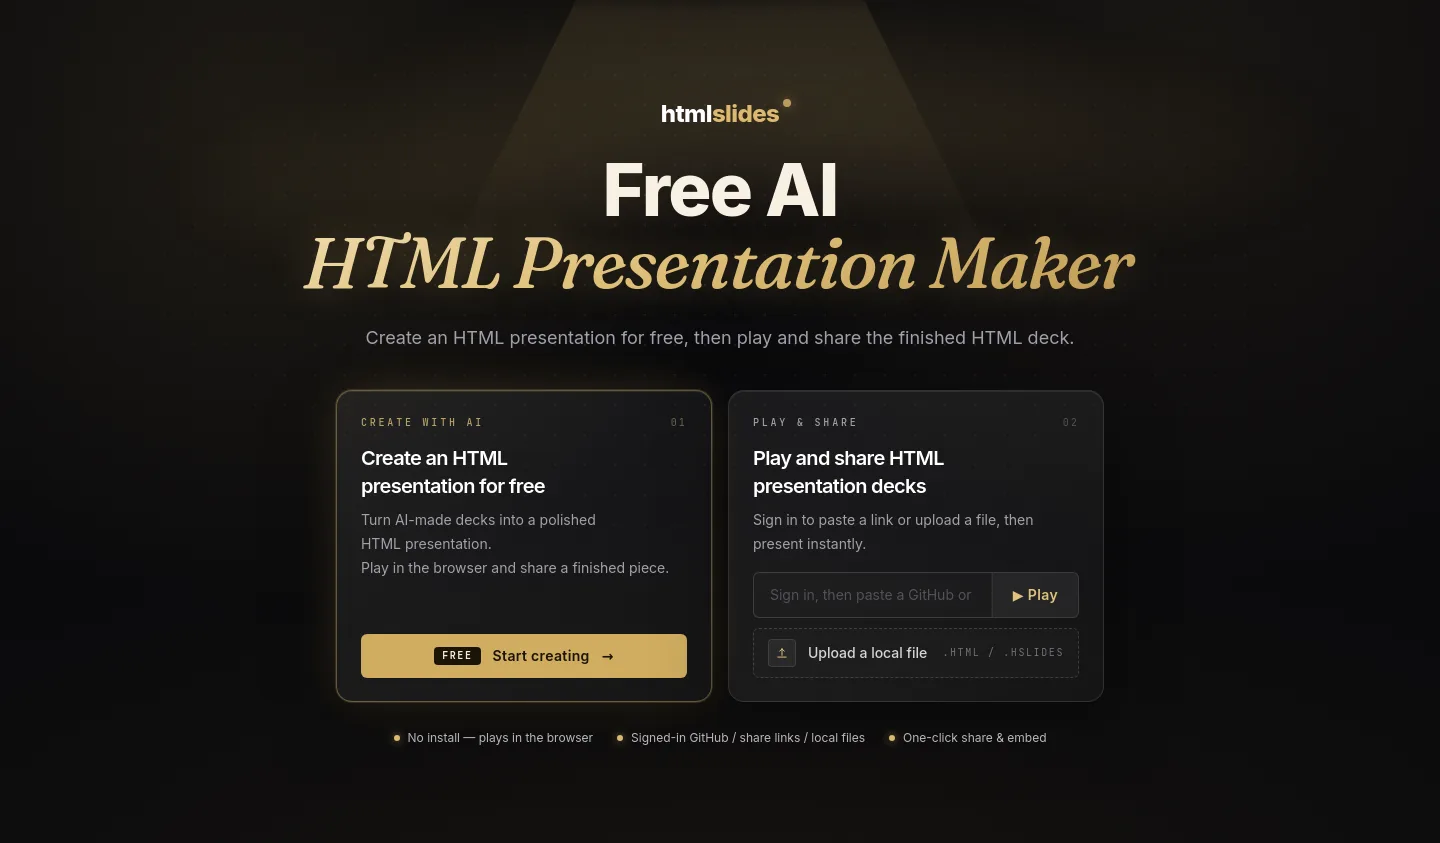
htmlslides.ai — a real Hero section
htmlslides.ai · Hero
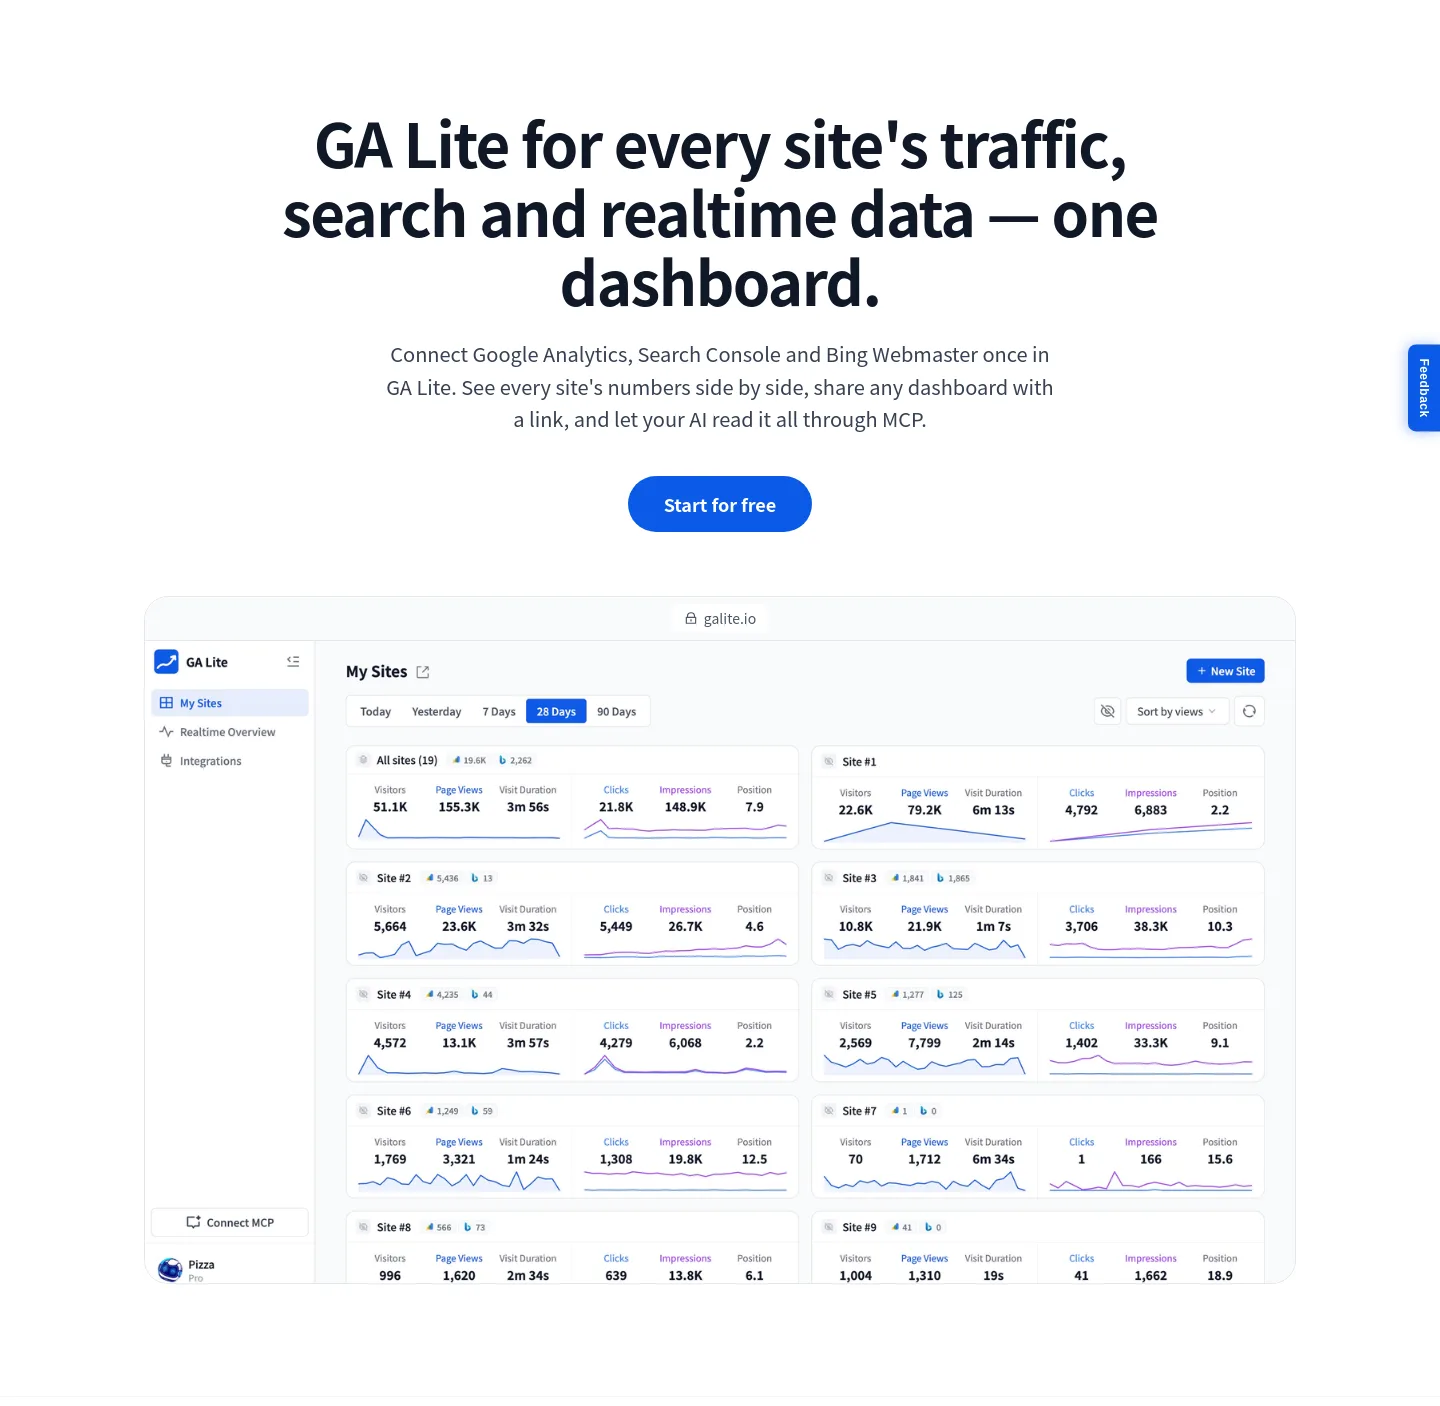
galite.io — a real Hero section
galite.io · Hero
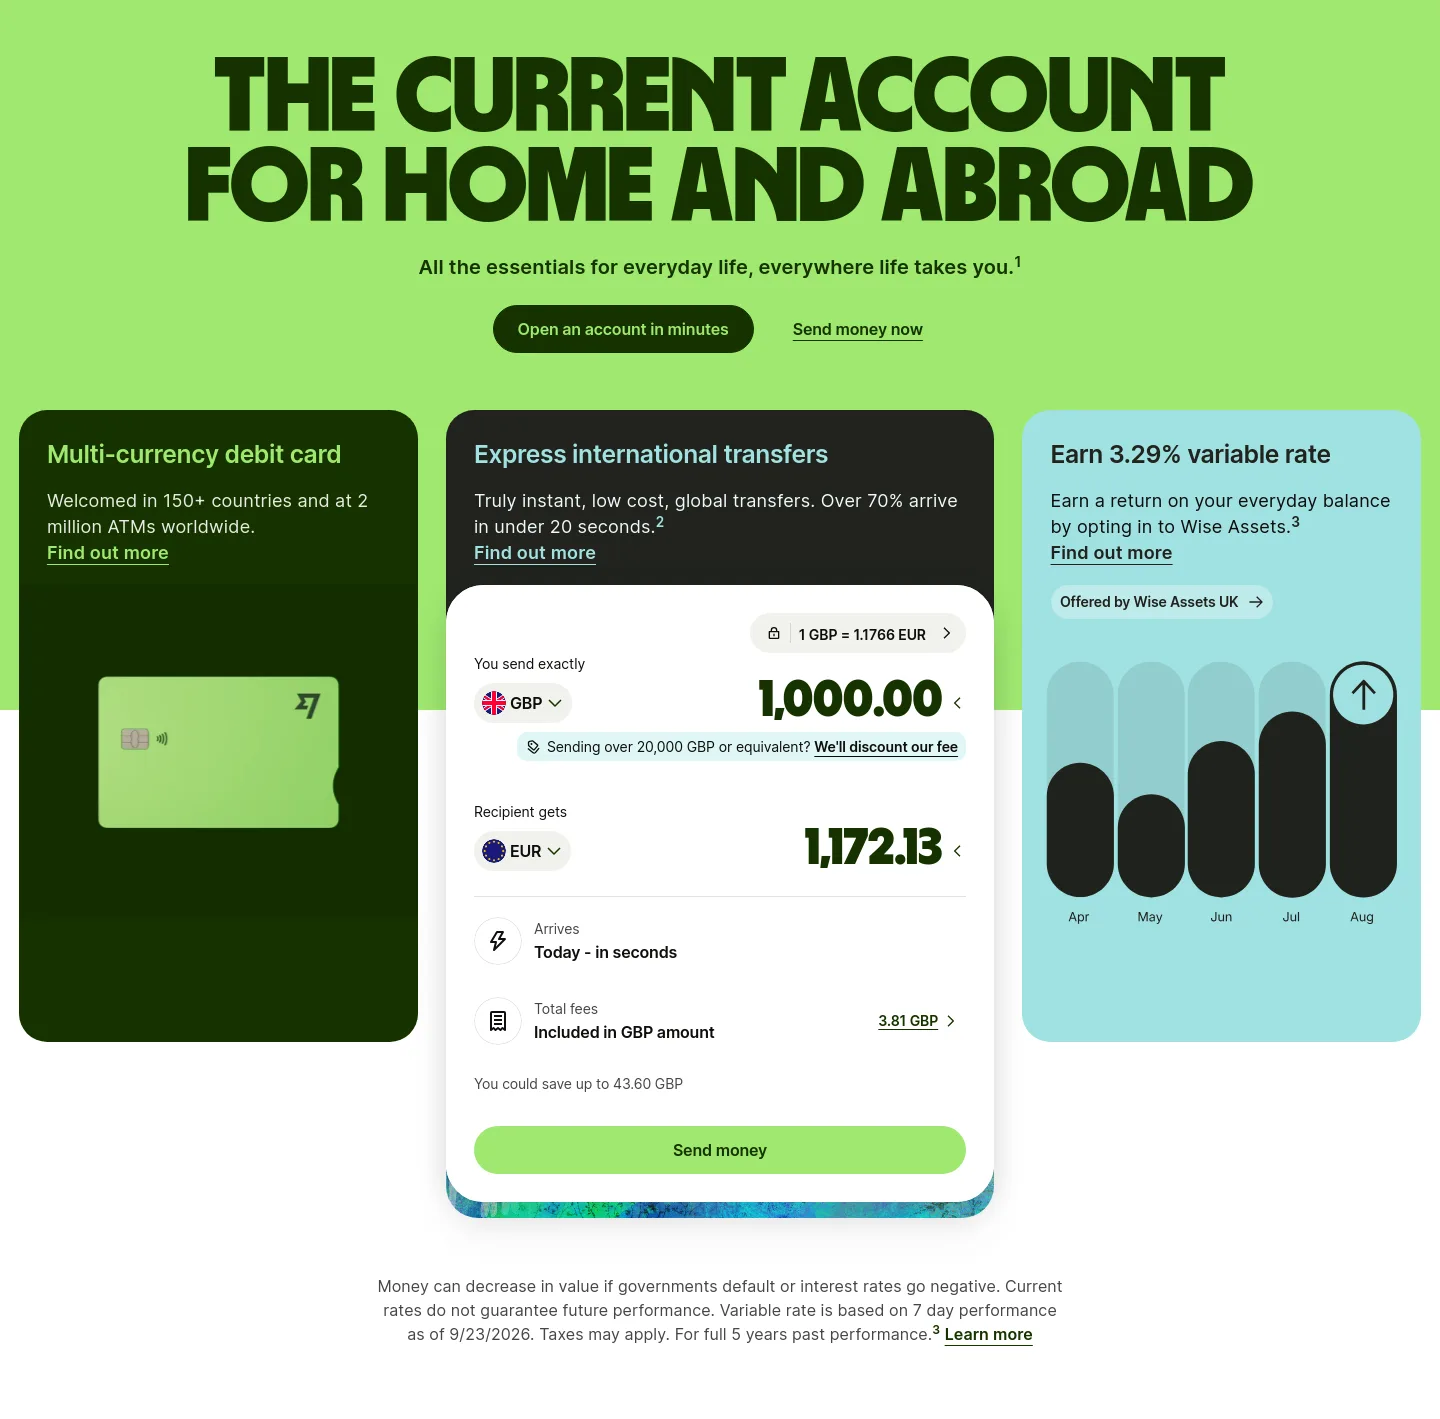
wise.com — a real Hero section
wise.com · Hero
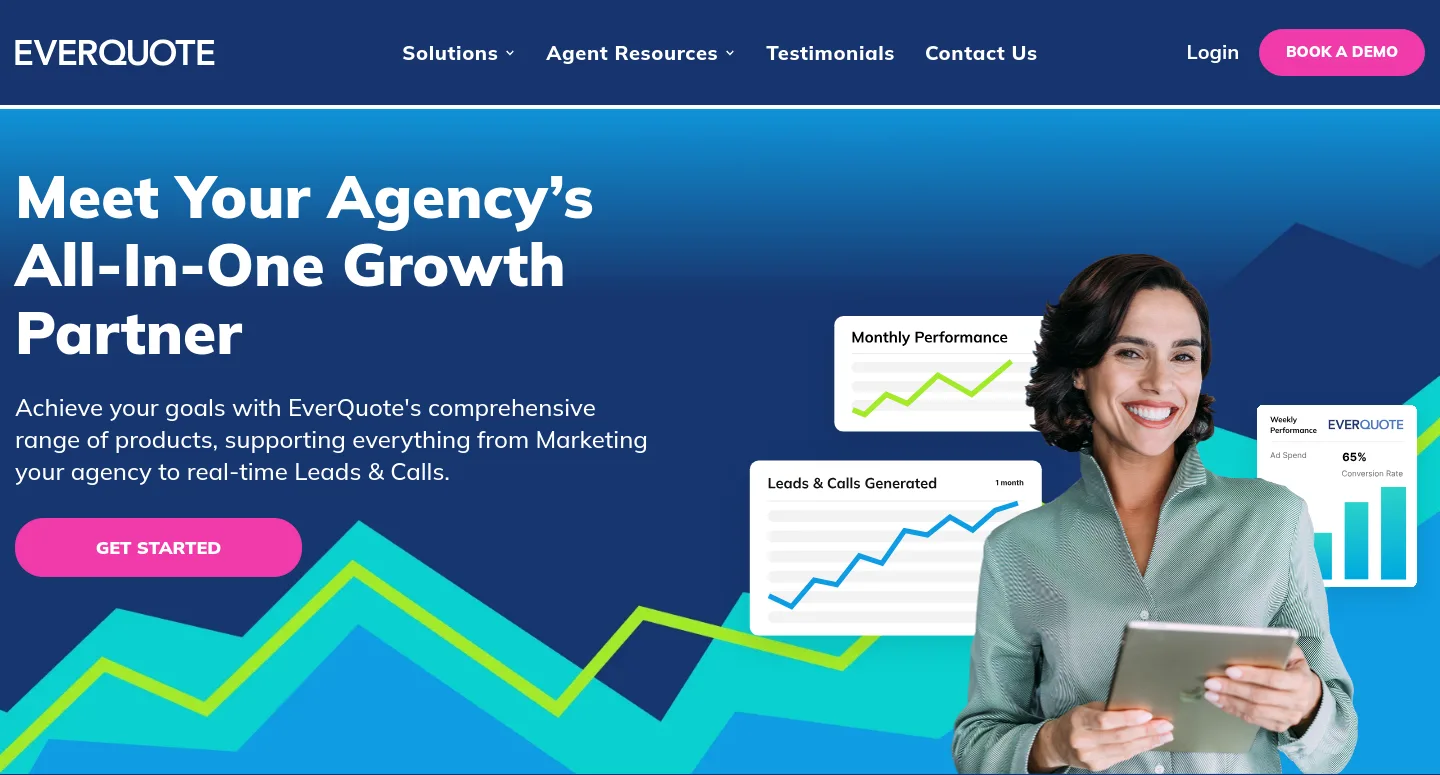
everquote.com — a real Hero section
everquote.com · Hero
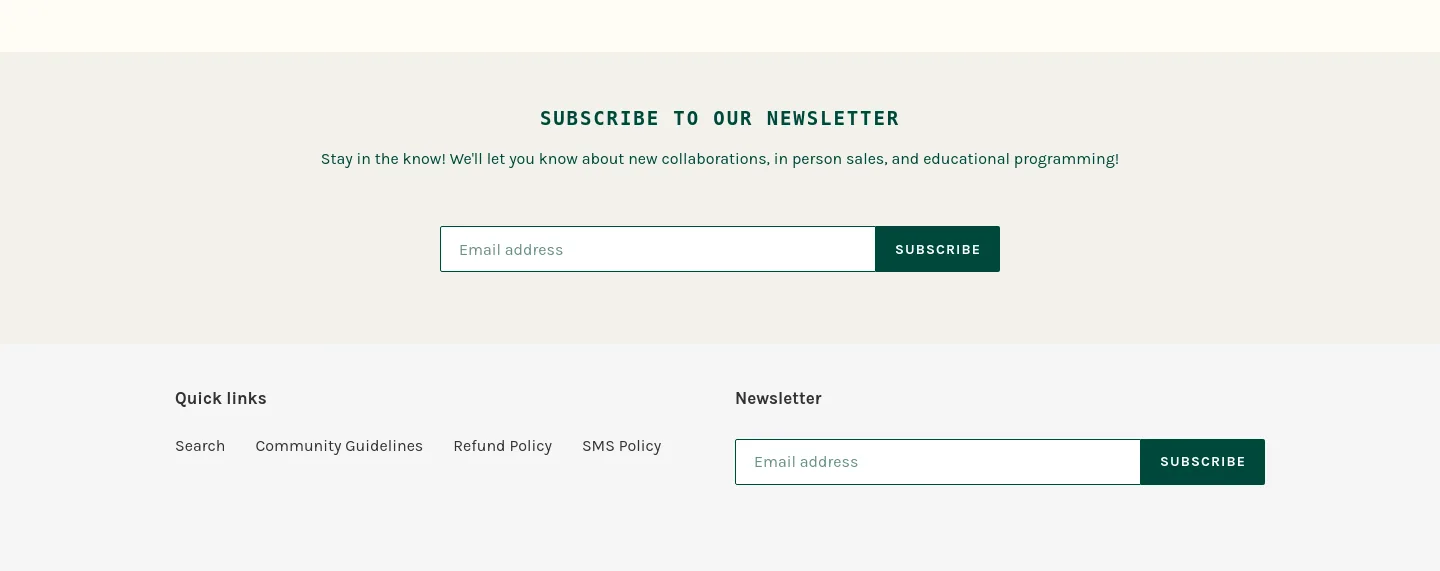
messarts.org — a real Email Capture section
messarts.org · Email Capture
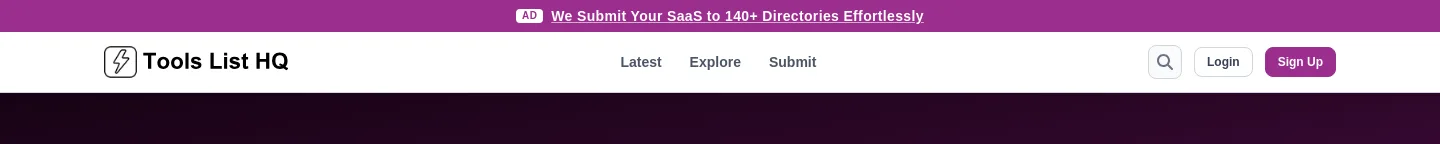
toolslisthq.com — a real Hero section
toolslisthq.com · Hero
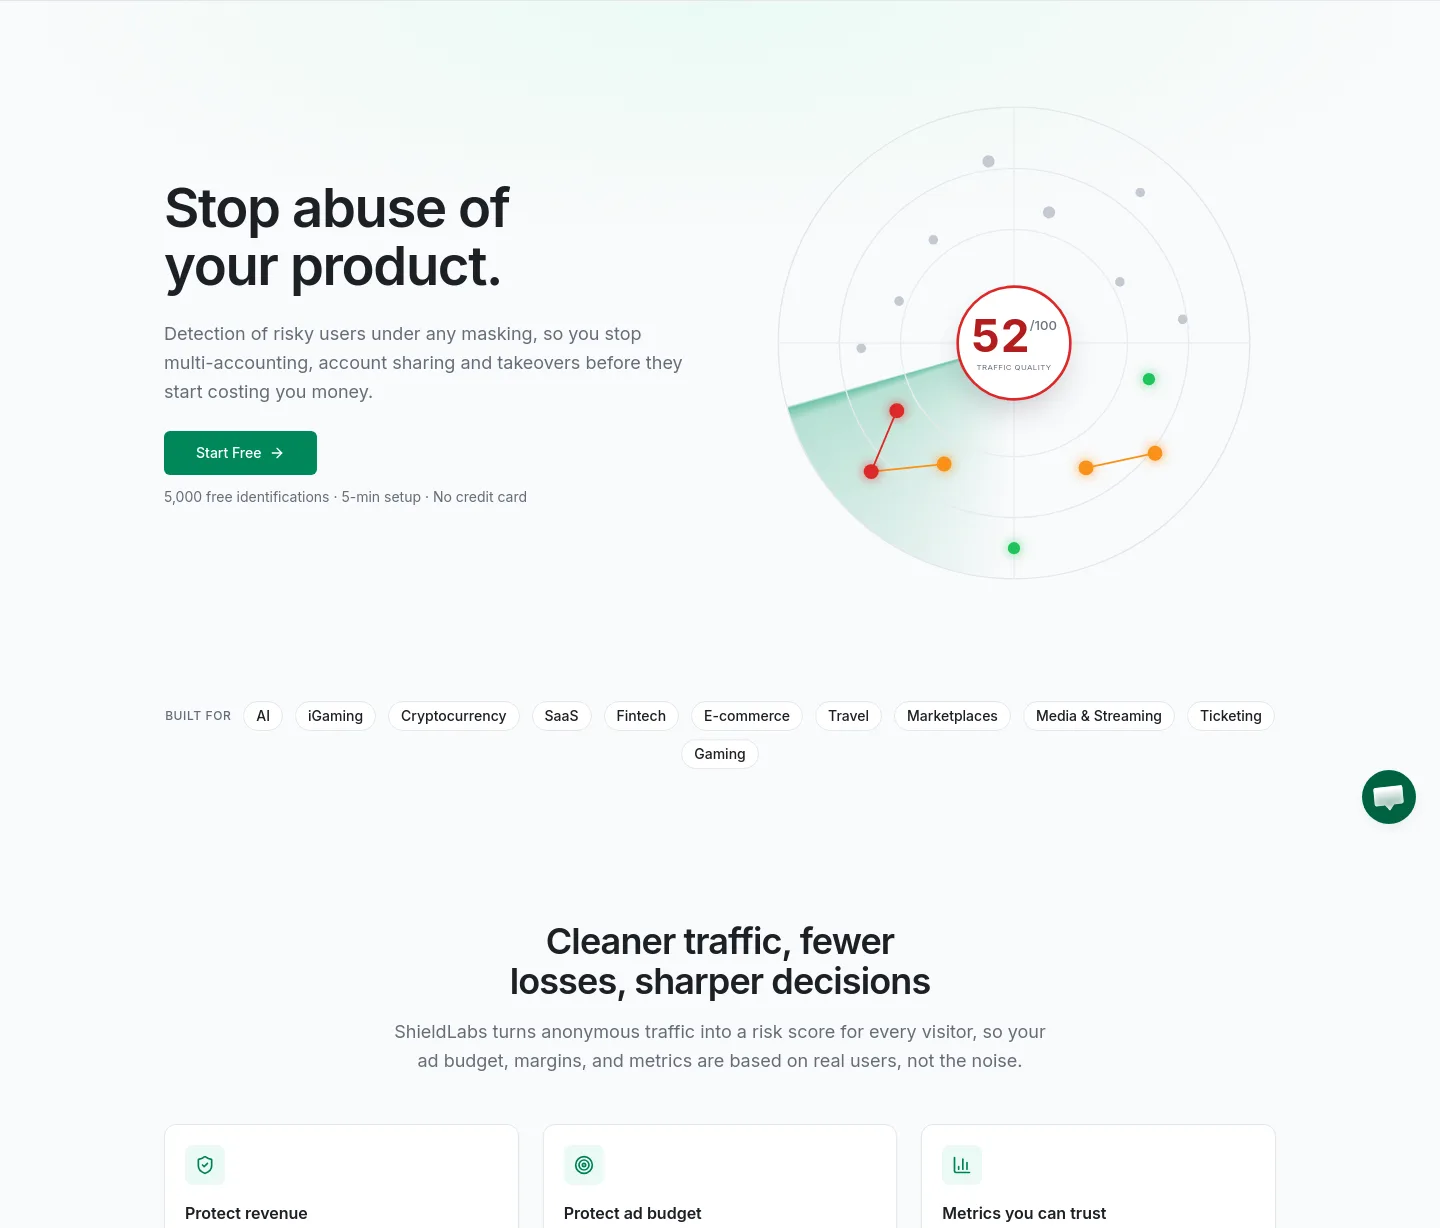
shieldlabs.ai — a real Hero section
shieldlabs.ai · Hero
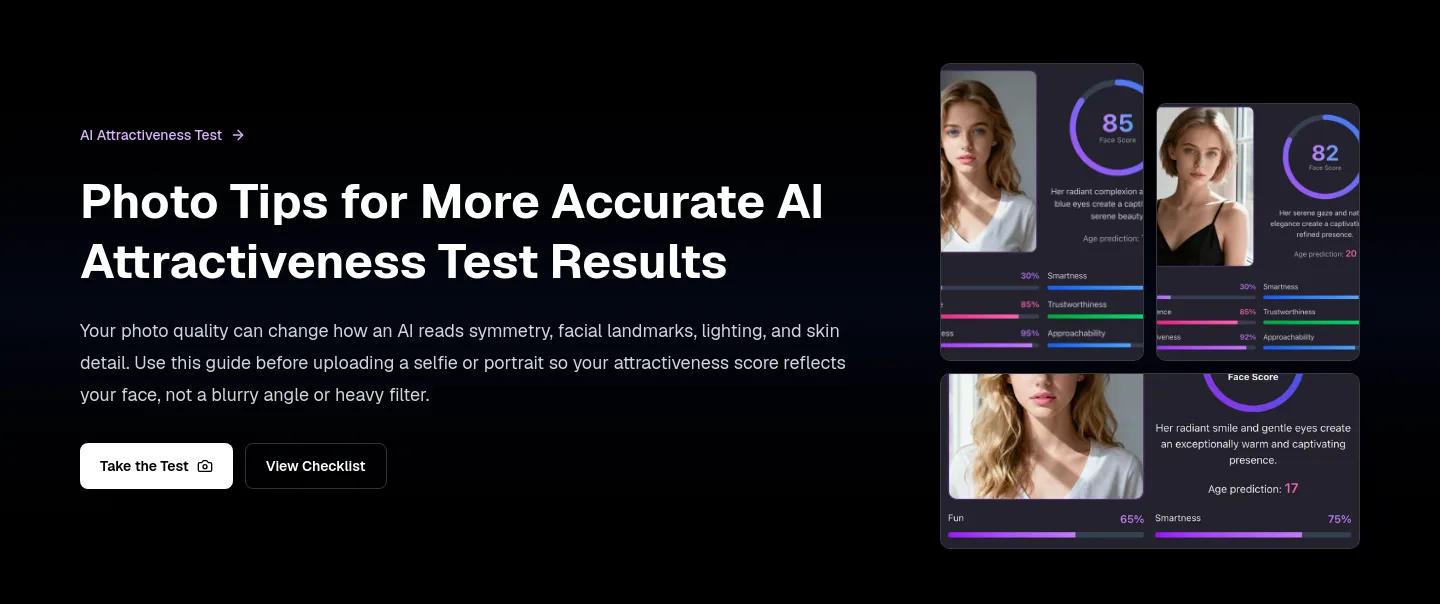
ai-attractivenesstest.com — a real Hero section
ai-attractivenesstest.com · Hero
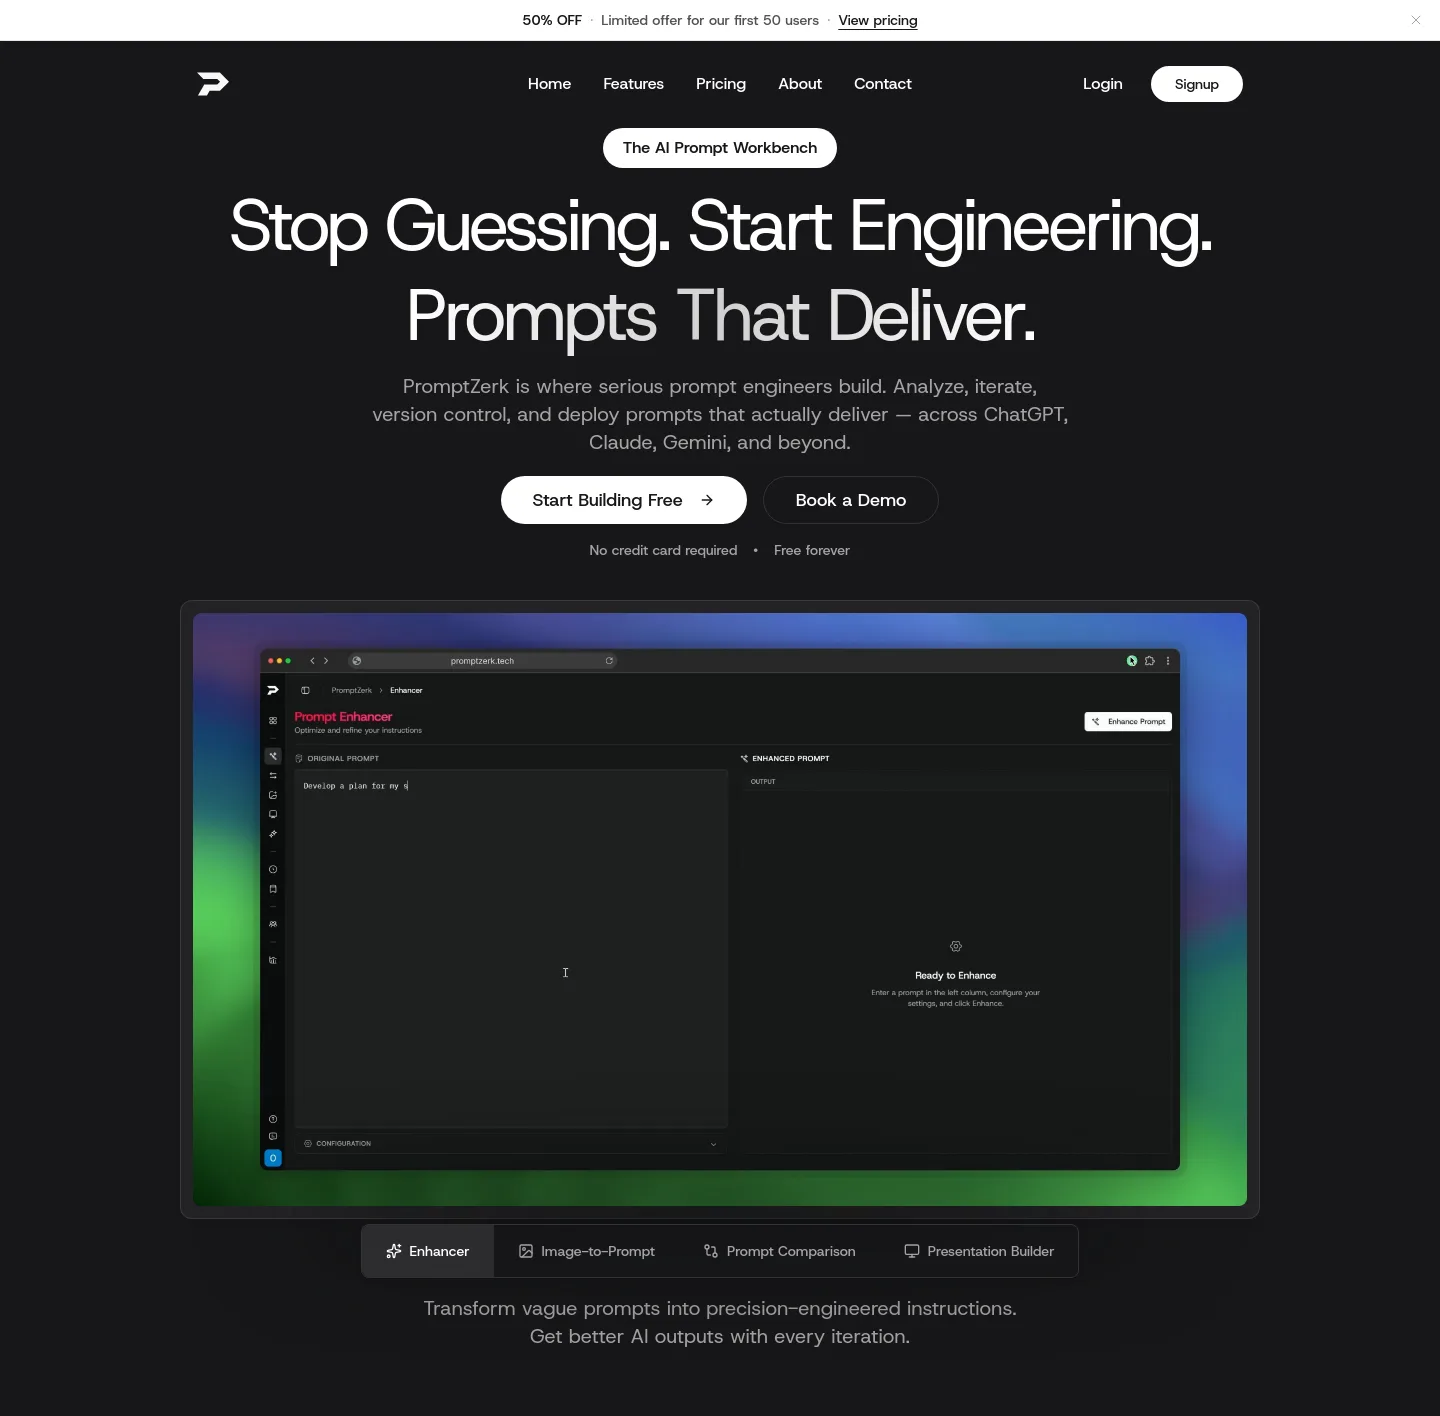
promptzerk.tech — a real Hero section
promptzerk.tech · Hero
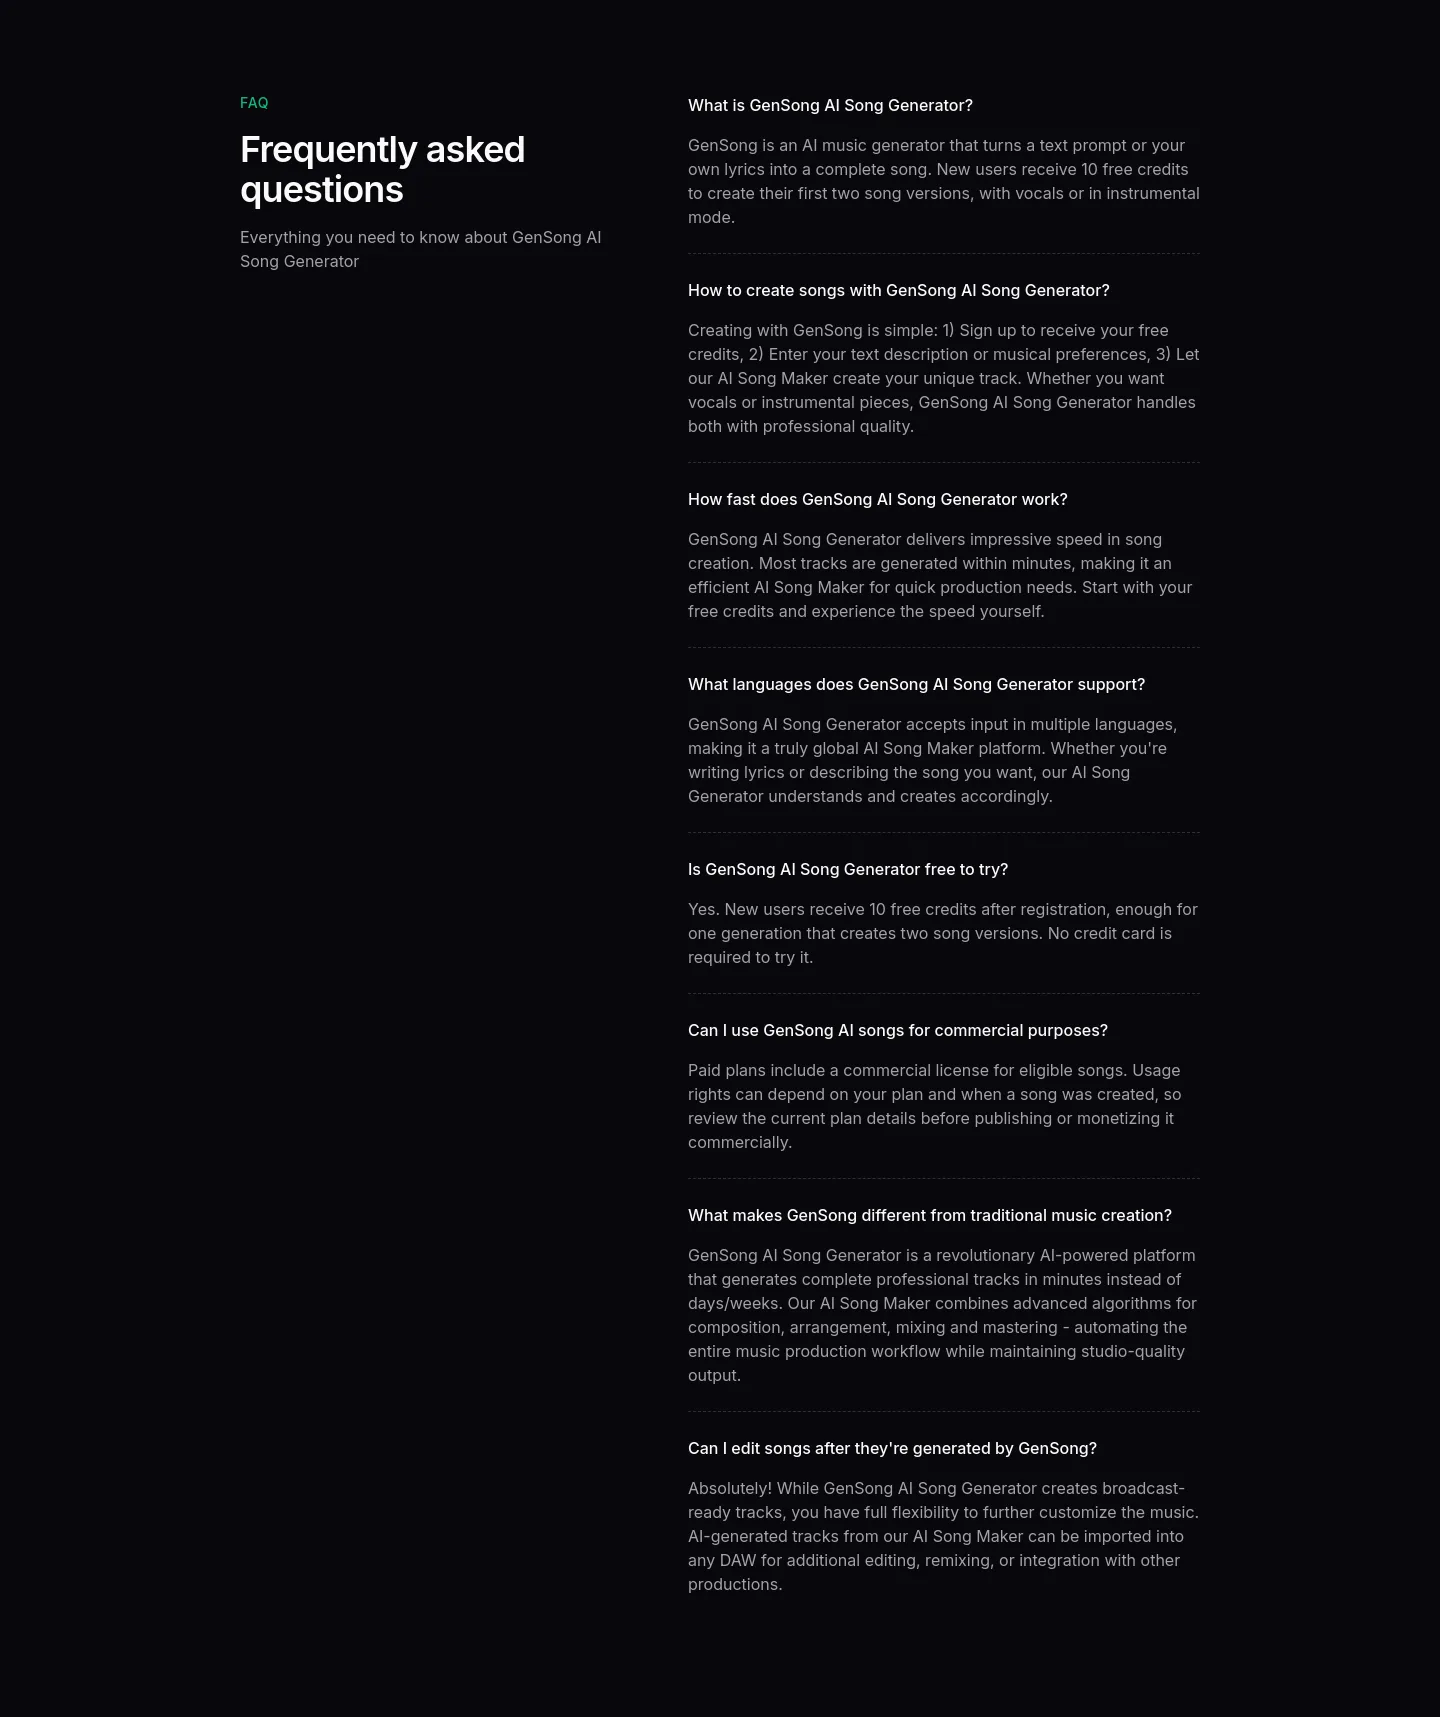
gensong.ai — a real FAQ section
gensong.ai · FAQ
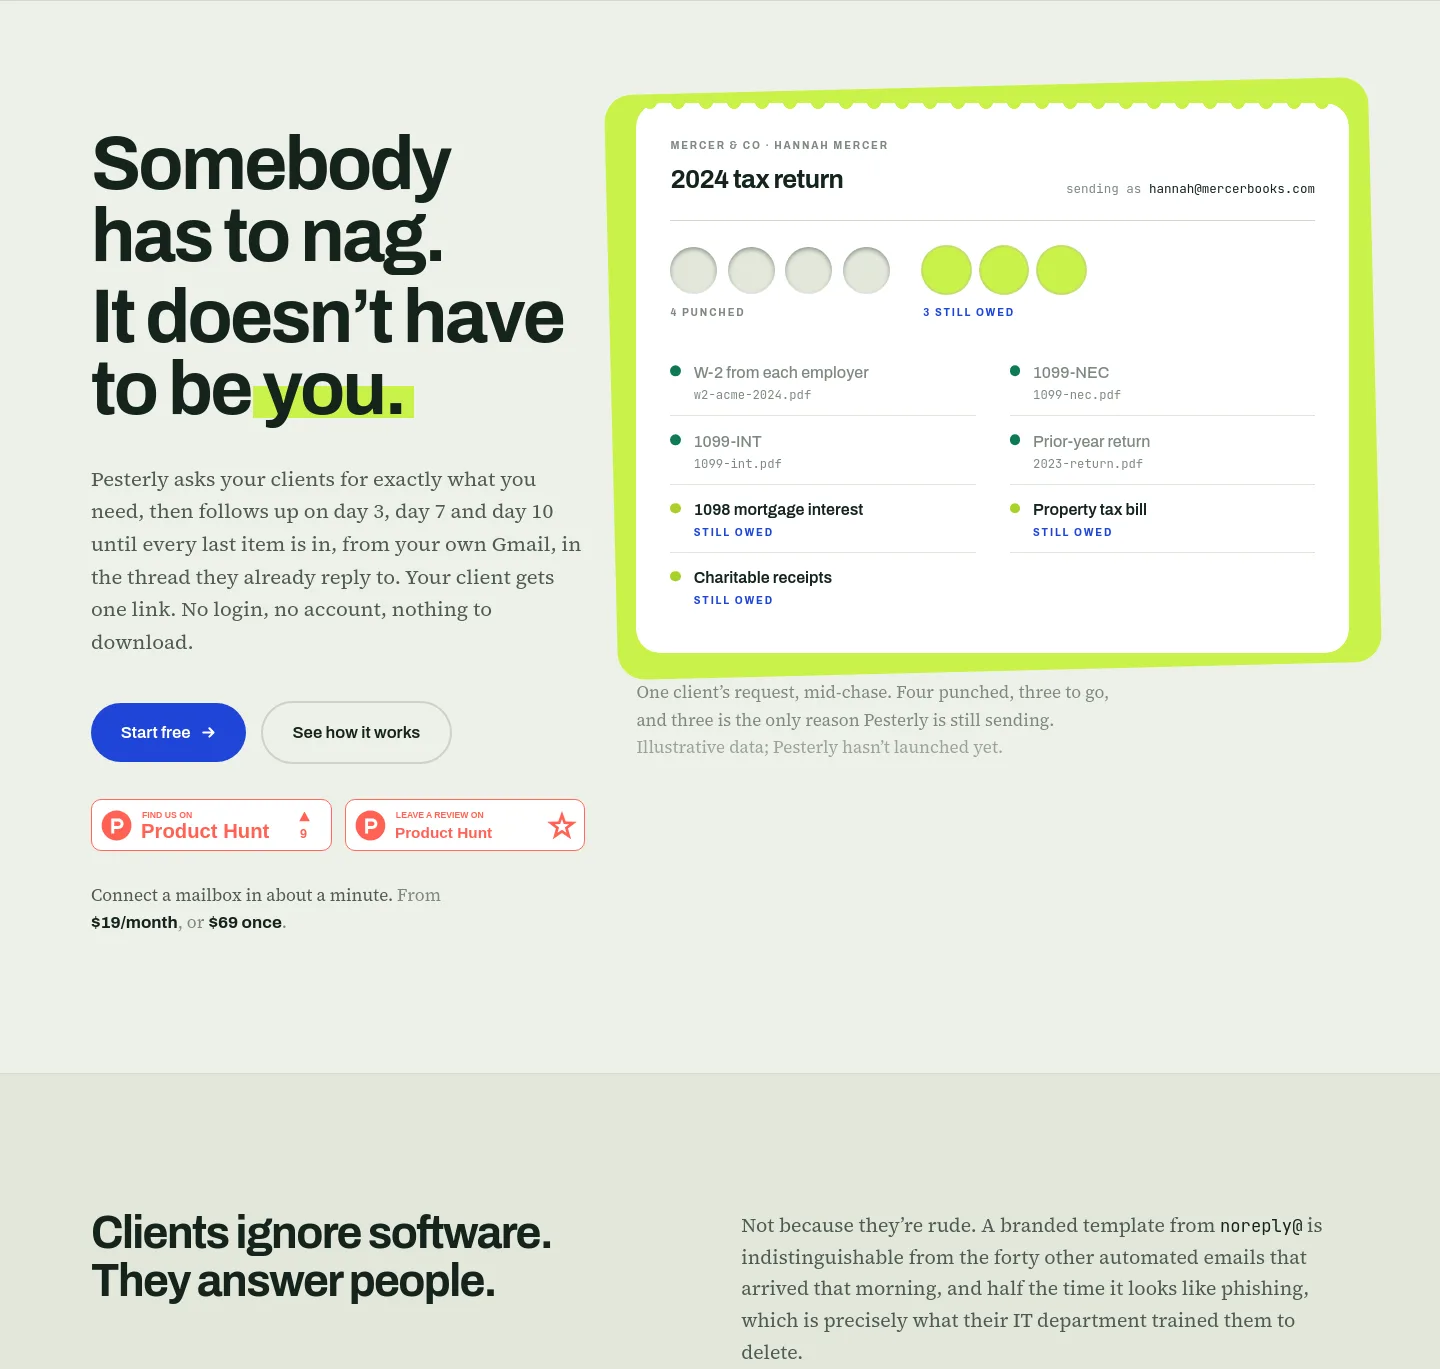
pesterly.com — a real Hero section
pesterly.com · Hero
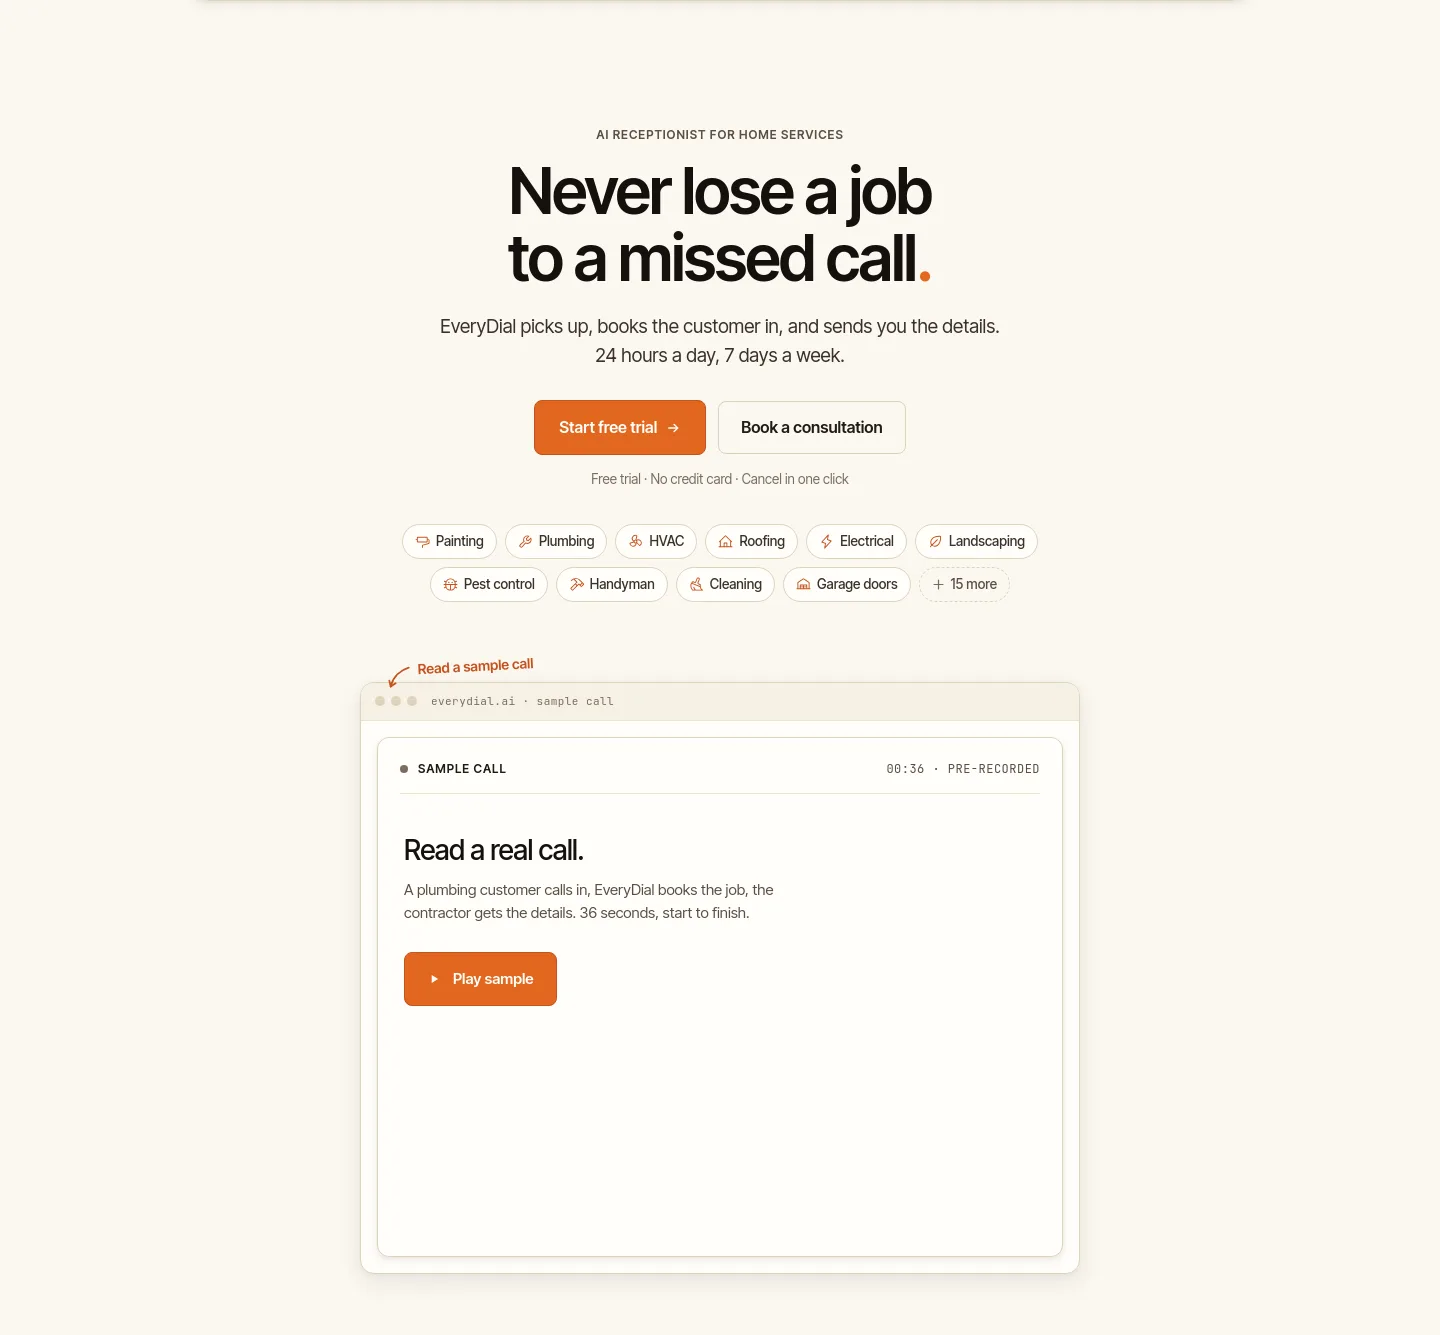
everydial.ai — a real Hero section
everydial.ai · Hero
2587 funnels x-rayed3919 pages measured10 section types

X-ray your own funnel · free, no signup required

Method: every crawled page is segmented into full-width bands and each band classified into a section archetype by deterministic DOM signals: no LLM, no opinion. Prevalence counts each archetype once per page, across pages crawled all the way to the footer (partial crawls are held back, not guessed). "Typically sits" = the average of the section's position within the page body (0 = top, 1 = bottom). Scoped to the pages we've crawled, not "the web"; auto-updating as the corpus grows.