Section Design Library

The bands real pages are built from

6,236 sections captured and categorized, from 2,335 funnels x-rayed.

Section

Showing 24 of 6236 sections
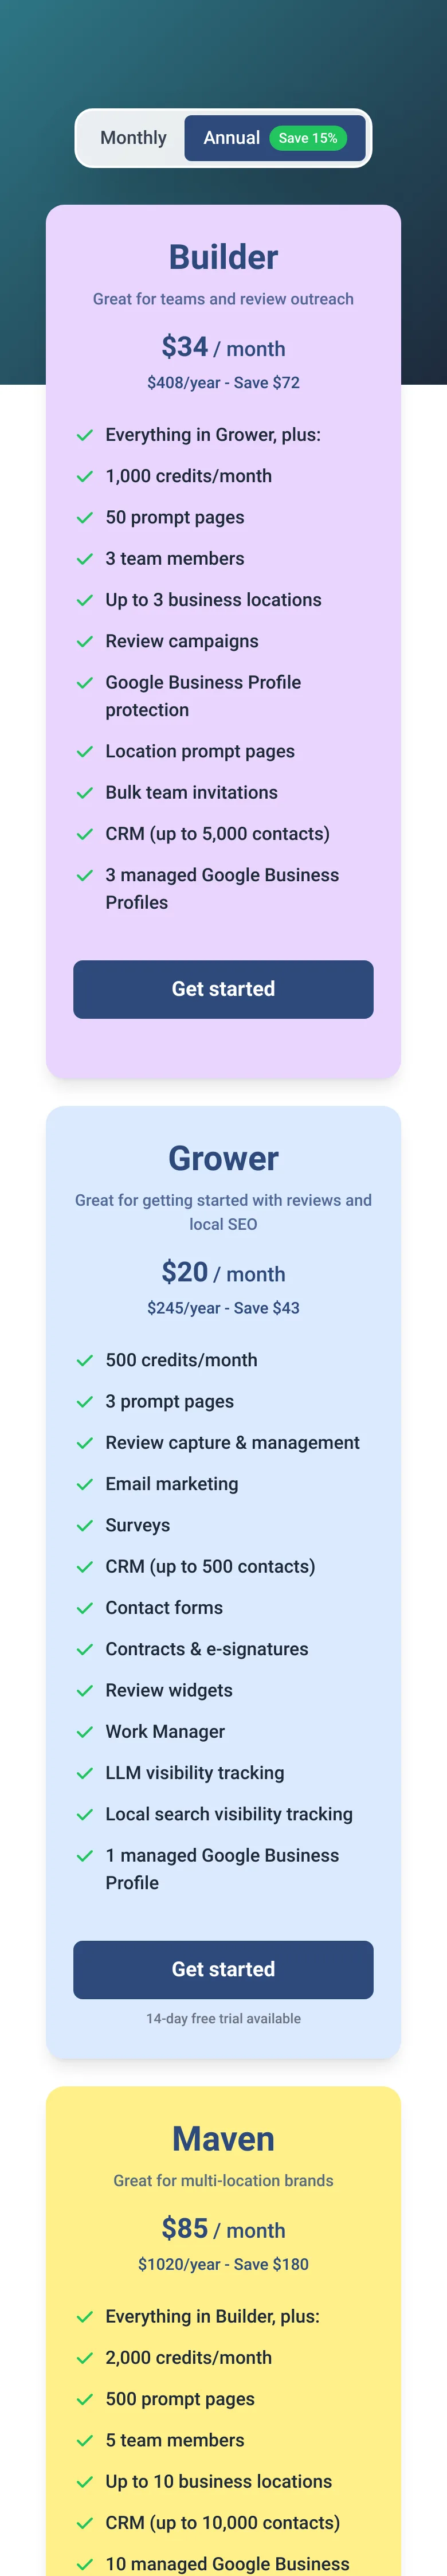
divinerone.com — a real Pricing section
divinerone.com · Pricing
promptreviews.app — a real FAQ section
promptreviews.app · FAQ
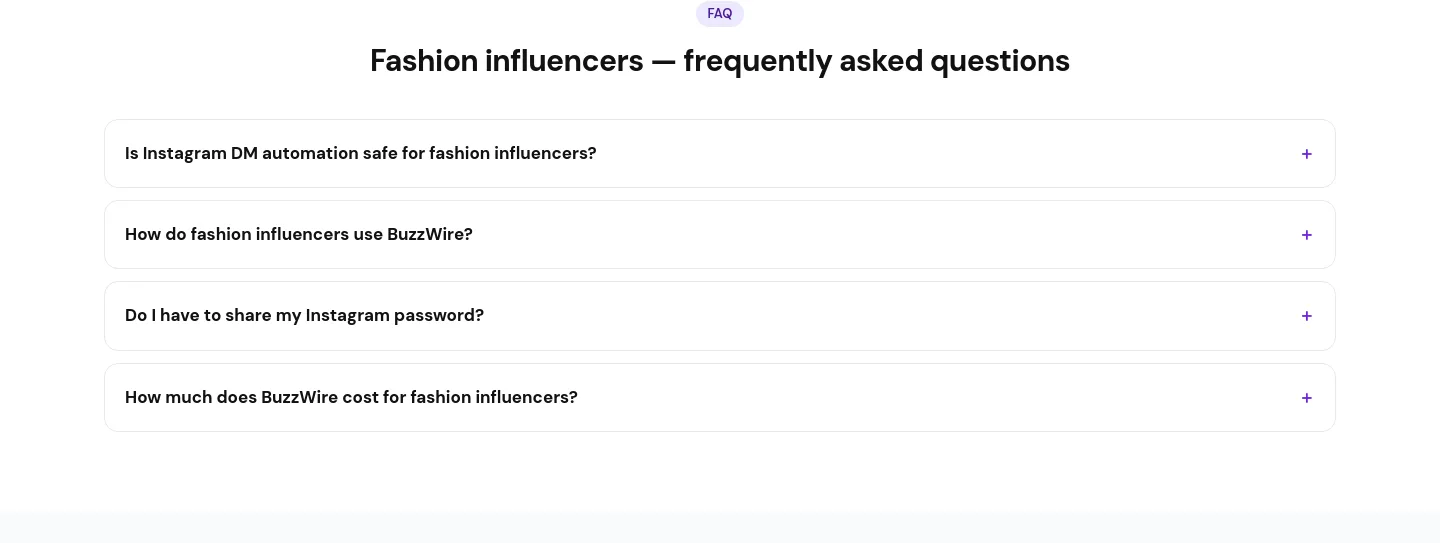
buzzwire.io — a real FAQ section
buzzwire.io · FAQ
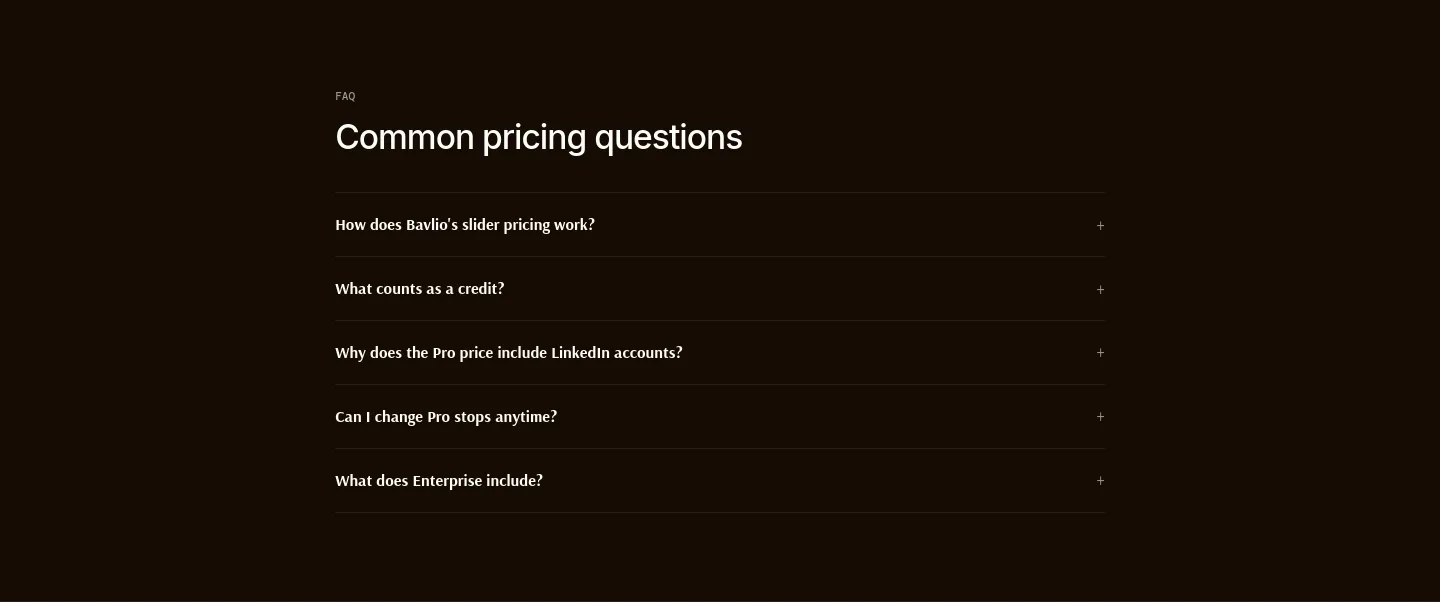
bavlio.com — a real FAQ section
bavlio.com · FAQ
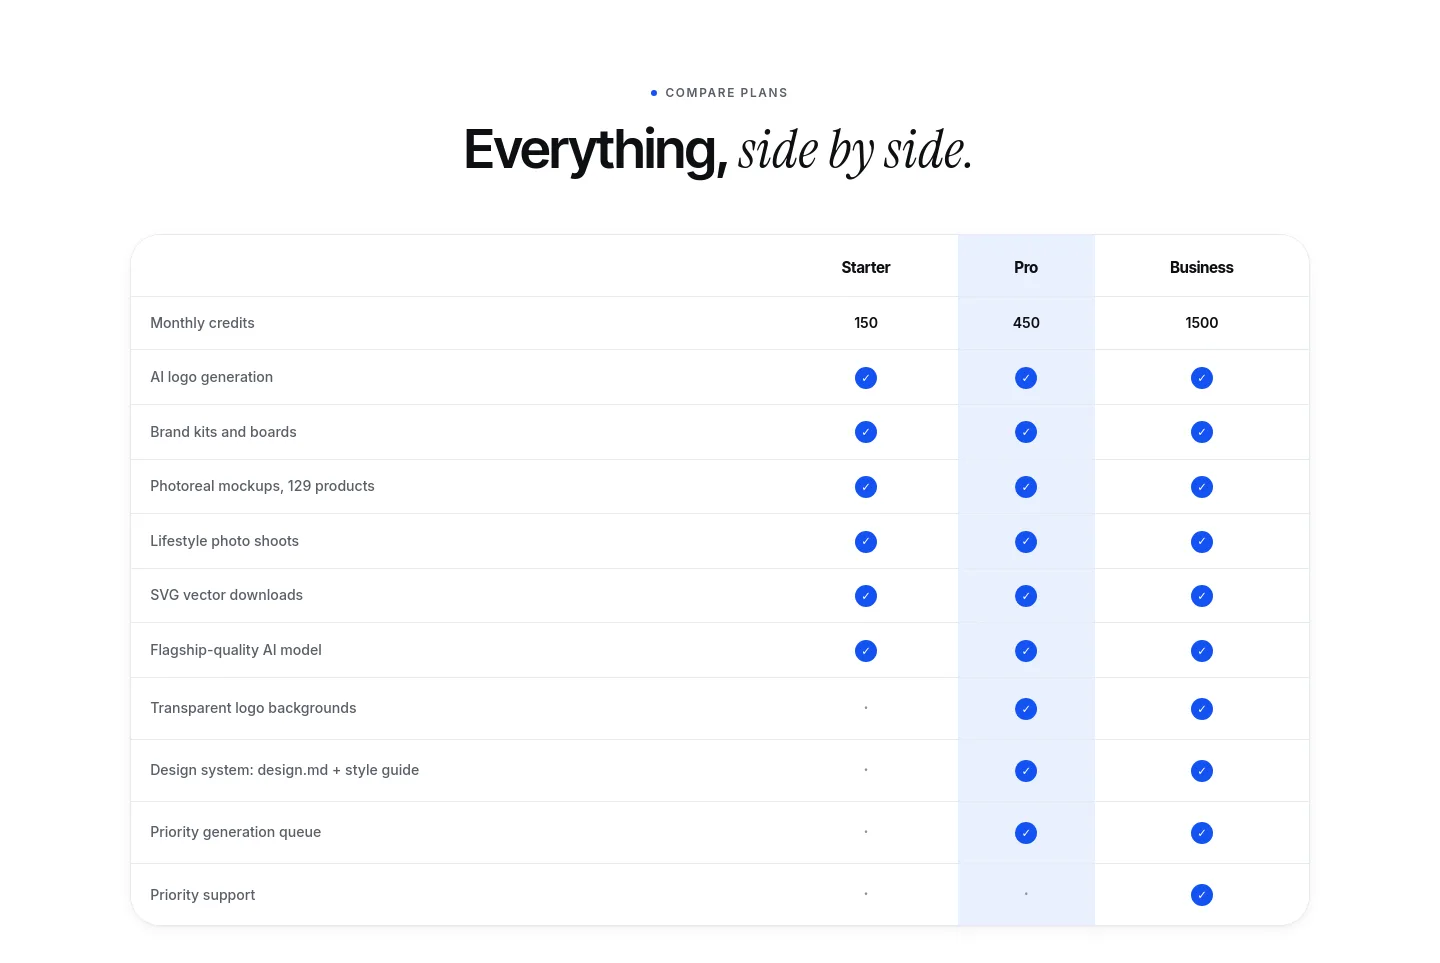
logofai.com — a real Comparison section
logofai.com · Comparison
easyinterview.life — a real CTA section
easyinterview.life · CTA
dabdash.com — a real Hero section
dabdash.com · Hero
magicshot.ai — a real CTA section
magicshot.ai · CTA
posteahora.com — a real CTA section
posteahora.com · CTA
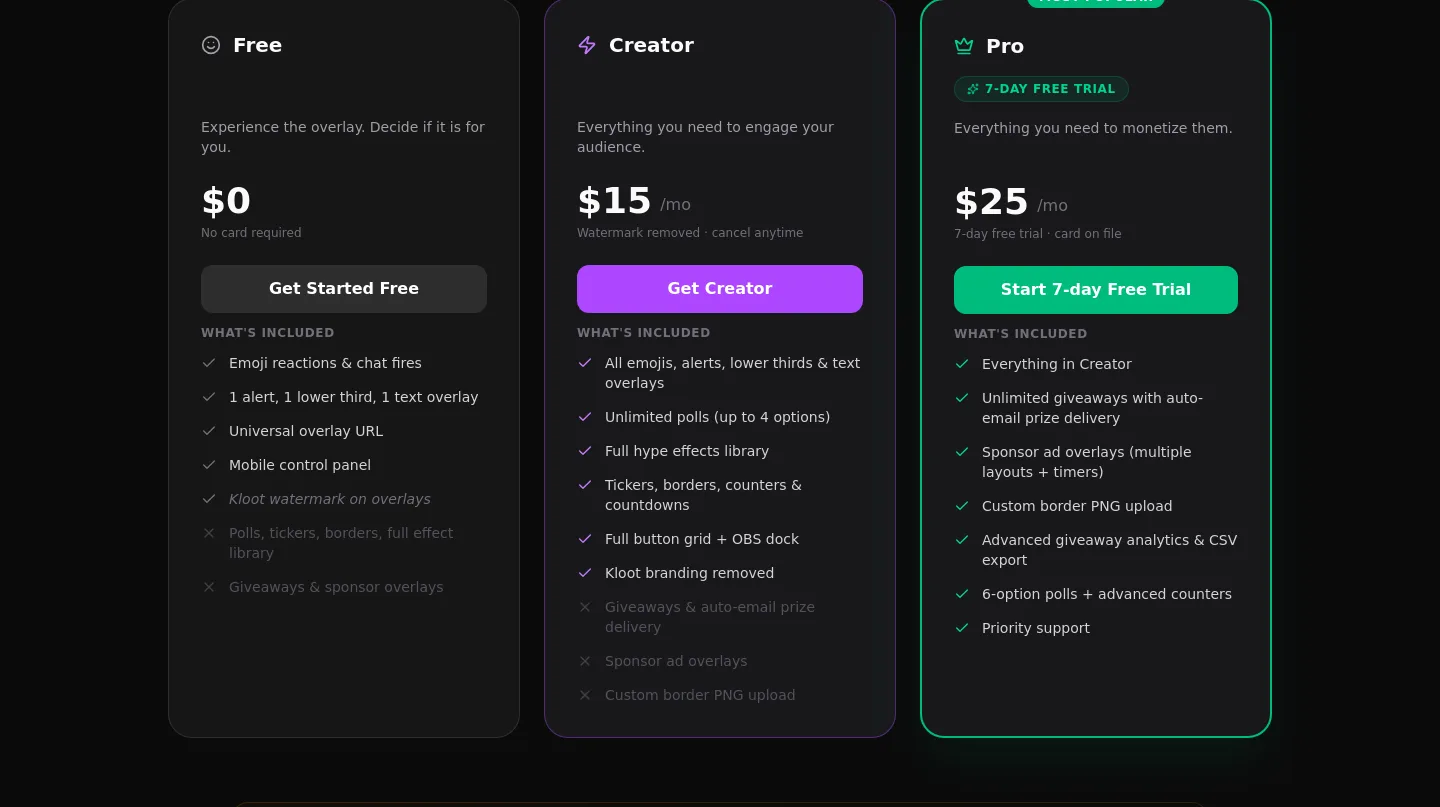
kloot.gg — a real Pricing section
kloot.gg · Pricing
timedsubs.com — a real Features section
timedsubs.com · Features
jobminglr.com — a real Features section
jobminglr.com · Features
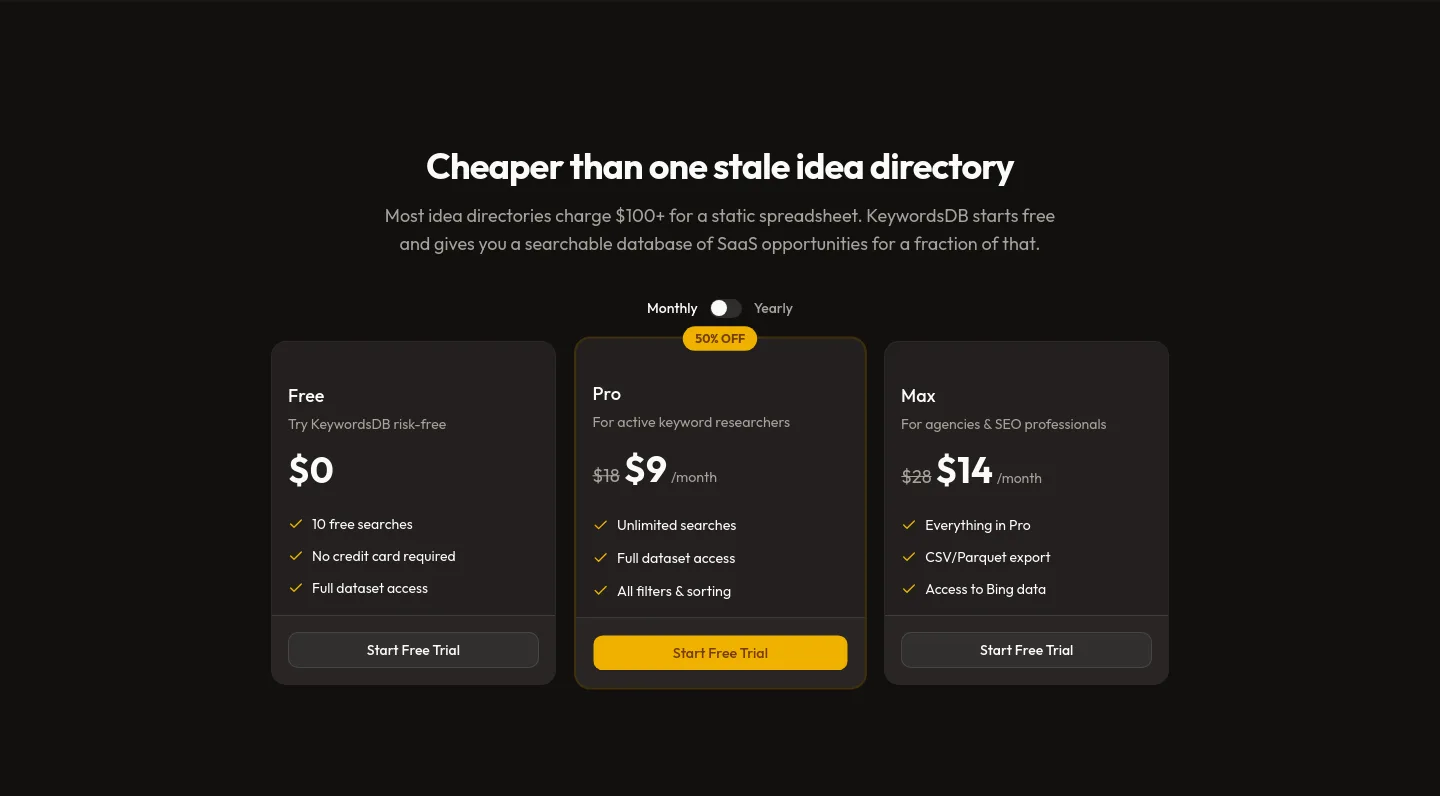
keywordsdb.com — a real Pricing section
keywordsdb.com · Pricing
doppio.sh — a real Stats section
doppio.sh · Stats
setsmart.io — a real Hero section
setsmart.io · Hero
altimateguide.com — a real Pricing section
altimateguide.com · Pricing
deepkolor.ai — a real FAQ section
deepkolor.ai · FAQ
cpages.ai — a real Comparison section
cpages.ai · Comparison
ottermind.ai — a real Hero section
ottermind.ai · Hero
bugshield.co.uk — a real FAQ section
bugshield.co.uk · FAQ
koozee.ai — a real Hero section
koozee.ai · Hero
lensgo.app — a real CTA section
lensgo.app · CTA
painonsocial.com — a real Hero section
painonsocial.com · Hero
interviewwatch.com — a real Pricing section
interviewwatch.com · Pricing
2335 funnels x-rayed3519 pages measured10 section types

X-ray your own funnel · free, no signup required

Method: every crawled page is segmented into full-width bands and each band classified into a section archetype by deterministic DOM signals: no LLM, no opinion. Prevalence counts each archetype once per page, across pages crawled all the way to the footer (partial crawls are held back, not guessed). "Typically sits" = the average of the section's position within the page body (0 = top, 1 = bottom). Scoped to the pages we've crawled, not "the web"; auto-updating as the corpus grows.